Network operations teams need six KPI categories to run a tight ship: incident management, performance and availability, security, SLA and customer experience, and maintainability. Each maps to a distinct operational outcome, incident metrics show how fast you recover, performance metrics show what users actually experience, and security metrics show how exposed you are between patches. The sections below break down the specific KPIs, how to measure them defensibly, and how to pilot the approach in weeks, not quarters.
TL;DR:
- Incident response KPIs, such as MTTR and incident escalation rate, vary significantly across agencies and require ongoing monitoring to identify process gaps.
- Performance metrics like latency percentiles and packet loss reveal tail-end network issues that averages and simple reports often hide.
- Combining active probes and passive telemetry, with clock synchronization, ensures accurate measurement of one-way delay and other IP performance parameters.
- Effective dashboards and tailored alert thresholds, especially at the P95 percentile, help prevent alert fatigue and enable proactive response before SLA violations.
- Setting realistic targets requires baseline data collection over at least 30 days, with KPIs mapped to specific services and ownership to guide focused improvements.
Table of Contents
- Core KPI categories every NOC should track
- How to measure network KPIs so the numbers hold up
- Turning KPIs into dashboards, alerts, and SLOs
- Finding chronic problems that averages hide
- Choosing the right KPIs and setting realistic targets
- A KPI-first pilot in practice
- The first 90 days: a practitioner checklist
- Running your KPI pilot on Netverge
- Sources
- FAQ
Core KPI categories every NOC should track
Incident management KPIs tell you how your team responds under pressure. Mean time to detect (MTTD) measures the interval between an issue occurring and someone noticing it. Mean time to resolve (MTTR) measures detection to full resolution. Incident volume and escalation rate round this out: a rising escalation rate often signals that frontline runbooks are not covering enough scenarios. A GAO review of federal cybersecurity incident response found that mean time to resolve incidents varies significantly among agencies, demonstrating wide variation in MTTR even within the same regulatory environment.

Performance and availability KPIs describe the network's daily behavior. Availability is expressed as a percentage of uptime over a given period. Latency is best reported as round-trip time at the P50, P95, and P99 percentiles rather than a single average, since averages hide the tail behavior that frustrates users. Packet loss is tracked as a percentage of lost packets per sample window, throughput in megabits or gigabits per second, and jitter in milliseconds of variance between packet arrivals.
Security KPIs quantify operational risk: mean time to detect a security event, the number of confirmed incidents per period, and patch compliance rate across your device fleet. SLA and customer-facing KPIs close the loop with the SLA compliance rate, breach count, customer-reported incident volume, and CSAT where applicable.
- Incident KPIs (MTTD, MTTR, incident volume, escalation rate) belong to NOC operators who act on them hourly.
- Performance and availability KPIs (uptime, latency percentiles, packet loss, throughput, jitter) sit at the operational layer but roll up into manager dashboards.
- Security and SLA KPIs (patch compliance, SLA breach count, CSAT) are managerial metrics reviewed weekly or monthly, not minute by minute.
How to measure network KPIs so the numbers hold up
Active probes send synthetic traffic (pings, synthetic transactions) to test a path on demand, useful for isolating a specific route or verifying an SLA claim. Passive telemetry observes real traffic flows and device counters, which shows what actual users experienced without adding load to the network. Most NOCs run both: active probes for baseline and SLA verification, passive telemetry for continuous visibility.
Clock synchronization matters more than most teams assume. One-way latency, delay measured from sender to receiver rather than round trip, requires synchronized clocks on both ends and reveals asymmetric routing problems that round-trip time can mask entirely.
- Adopt ITU-T Y.1543 and related measurement recommendations for IP performance parameters; they define standard methods for one-way delay, packet loss, and QoS measurement so results are comparable across vendors and domains.
- Reference IETF IP Performance Metrics (IPPM) work alongside ITU standards when building measurement pipelines that span multiple network operators.
- Set probe cadence based on the KPI's volatility: latency and packet loss benefit from continuous or minute-level sampling, while throughput and jitter can tolerate five-minute intervals without losing operational value.
- Balance retention against cost: keep high-resolution data for 30 to 90 days for troubleshooting, then downsample to hourly or daily aggregates for long-term trend reporting.
Turning KPIs into dashboards, alerts, and SLOs
A dashboard built for an operator should show live incident status, current latency percentiles, and active alerts. A manager's view rolls those into weekly trends and SLA compliance summaries. An executive heatmap distills everything into a handful of colors across sites or services. Building one dashboard for all three audiences usually satisfies none of them.
Alert fatigue kills NOC effectiveness faster than any single outage. Deduplicate repeated alerts from the same root cause, suppress known maintenance windows, and route alerts to the team that owns the affected service rather than broadcasting to everyone. A network performance management workflow built around clear ownership reduces the noise that buries real signals.
Service Level Objectives (SLOs) are the internal targets you set from KPI percentiles and business impact, distinct from the SLA you commit to customers. If P95 latency for a critical application needs to stay under 100 milliseconds to avoid user complaints, that becomes your SLO, with alert thresholds set below the SLO so operators act before the SLA is at risk.
- Use percentiles, not means, when setting alert thresholds for latency and packet loss.
- Set reporting cadence by audience: operators need real-time views, managers need weekly summaries, executives need monthly or quarterly rollups.
- Assign a named owner to every KPI that appears on a dashboard, since an unowned metric rarely gets acted on.
Pro Tip: Set your alert threshold at the P95 value, not the mean, so you catch degradation before most users notice it.
Finding chronic problems that averages hide
Averages smooth out the intermittent packet loss spike or the five-minute latency blip that happens twice a week and never shows up in a monthly report. P95 and P99 tail-latency analysis surfaces exactly these patterns, because a chronic issue that affects 2% of sessions barely moves a mean but shows up clearly at the 99th percentile.
Correlating across syslogs, flow data, and performance metrics is how experienced teams find recurring root causes that a single data source cannot reveal. Research on chronic network conditions from statistical correlation studies demonstrated that correlating multiple measurement streams uncovered low-duration, recurring events in a production tier-1 network that manual troubleshooting had missed entirely.
- Automated anomaly detection and triage shorten MTTD by flagging deviations before an operator would notice them manually.
- Reserve lab reproduction for issues that resist correlation, when the pattern is confirmed but the trigger is not yet isolated.
- Pilot the approach at 2 to 3 sites first, validating that your measurement pipeline catches known issues before scaling network-wide.
Automated diagnostics built into your monitoring stack reduce the manual correlation work operators would otherwise do by hand.
Choosing the right KPIs and setting realistic targets
Start from the business outcome you are protecting, not the metrics that are easiest to collect. A customer-facing application might need 3 to 5 KPIs: availability, P95 latency, and SLA compliance, while a backend batch process might only need throughput and error rate.
- Map each service to its 3 to 5 most relevant KPIs rather than tracking everything uniformly across the environment.
- Confirm each KPI is actionable (someone can respond to it), measurable (you have a reliable data source), ownerable (a specific role is accountable), and comparable (the method matches across time periods).
- Set a baseline from at least 30 days of historical data before defining a target, then express the target as a percentile tied to acceptable business impact.
- Watch for metric overload: MSPs managing dozens of client networks need standardized KPIs across accounts, while an in-house NOC can afford more service-specific customization.
A KPI-first pilot in practice
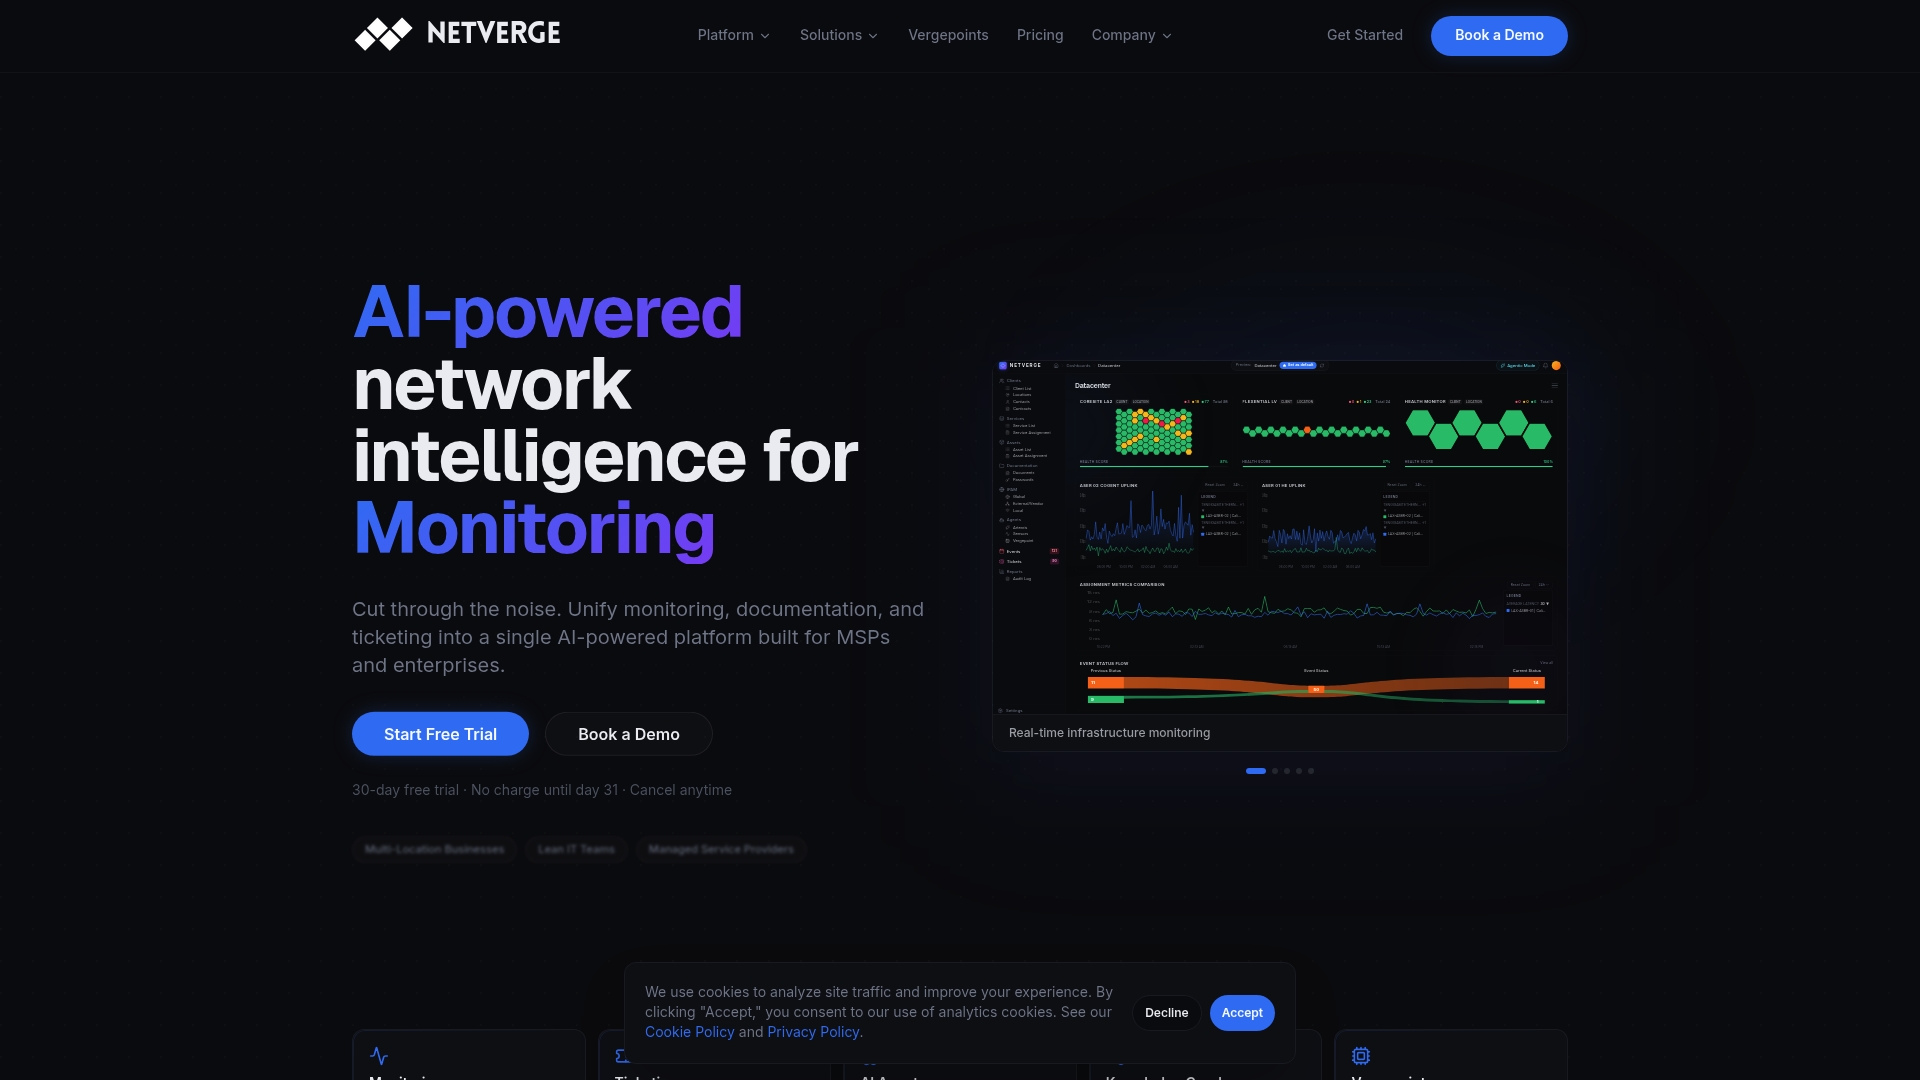
Netverge consolidates monitoring, documentation, ticketing, and automation into a single platform, which matters when you are trying to instrument these KPIs without stitching together five disconnected tools.
- A practical pilot: deploy Wi-Fi monitoring at 2 to 3 sites and track availability, latency percentiles, and incident volume for two to four weeks.
- Hardware Vergepoints add on-site visibility for KPIs that require a physical vantage point, like local packet loss or jitter.
- Correlation across logs and metrics, combined with automated triage, is designed to reduce alert noise and shorten detection time without adding headcount.
The first 90 days: a practitioner checklist
Establish baselines for your top 5 KPIs in the first two weeks. Build operator, manager, and executive dashboards by week four. Run your pilot measurements at 2 to 3 sites through week eight, tuning alert thresholds as false positives surface. Finalize SLOs by day 90 based on what the pilot data actually showed, not what looked reasonable on paper.
The most common pitfall is setting targets before collecting a baseline. Chasing an arbitrary 99.9% availability number without knowing your actual historical performance sets teams up to miss targets they never needed in the first place.
— Jim
Running your KPI pilot on Netverge
Netverge maps directly onto the KPI categories covered above: real-time monitoring for availability and latency, AI-powered ticketing for MTTD and MTTR tracking, and knowledge graphs that keep documentation aligned with what your dashboards show.
The Starter Package is $299 per month, with Hardware Vergepoints available at $49 per month per device for the on-site visibility your pilot needs. If chronic packet loss or alert fatigue is part of your problem, a correlated packet loss monitoring approach paired with the right hardware placement tends to surface issues faster than log review alone. For teams that also want managed cybersecurity support alongside their monitoring pilot, NEXTmsp's cybersecurity services cover incident response and resilience testing. Start a free trial to run your own 2 to 3 site pilot and see how the KPIs described here look on your own network.
Sources
The ITU-T Y.1543 measurement recommendations, GAO's incident resolution findings, and NTIA's BEAD performance measures policy each ground a different KPI category in a documented, testable standard.
- GAO report on federal agency cybersecurity incident response
- ITU-T Y.1543 and related ITU measurement recommendations
- Troubleshooting chronic conditions in large IP networks (NICE)
FAQ
What are the 5 key performance indicators in operations?
Operations teams typically track incident response time, availability or uptime, throughput, error or defect rate, and customer satisfaction. In network operations specifically, these translate to MTTR, uptime percentage, packet loss or throughput, security incident count, and SLA compliance rate.
What are the top 3 KPIs for network operations?
Most NOCs prioritize MTTR (how fast incidents get resolved), availability (uptime percentage), and SLA compliance rate, since these three most directly reflect what customers and business stakeholders experience. Latency percentiles are a close fourth for any team supporting real-time applications.
What are the key performance metrics used in networking?
Core networking metrics include latency (often measured at P95 and P99, not just the mean), packet loss percentage, throughput, jitter, and availability. Standards bodies like the ITU provide measurement recommendations for IP performance parameters to keep results comparable across networks and vendors.
What are the key performance indicators for IT operations?
IT operations KPIs generally span incident management (MTTD, MTTR), performance and availability, security (patch compliance, incident count), and SLA or customer satisfaction metrics. The right mix depends on which services the team supports, but most organizations track KPIs from all four categories rather than relying on just one.