Cut detection time by focusing on symptom-based SLO alerts, unified telemetry, automated enrichment, and tested alert logic. Teams that center alerting on service-level objectives rather than raw server metrics catch real problems faster and page on fewer false signals, according to Google's SRE workbook. Combined with synthetic checks on critical user journeys and automated triage, these levers consistently shorten detection windows.
TL;DR:
- Focusing on symptom-based alerts and auto-enrichment can reduce mean time to detect incidents, often cutting detection windows significantly.
- Using multi-window burn-rate alerts with both short and long monitoring windows balances false positives and detection speed, especially for high-severity issues.
- Prioritizing metrics and synthetic checks for alerting, with logs reserved for post-detection investigation, prevents delays caused by high-fidelity signals.
- Validating monitoring systems with binary, rule, and routing tests weekly helps ensure alert reliability before they are needed in real incidents.
- Clear incident roles, a shared process, and practiced handoffs are critical for shortening detection to containment times.
Table of Contents
- What Is MTTD and How Do You Measure It?
- Why Reducing MTTD Matters for Reliability and Cost
- Core Strategies to Cut Detection Time Now
- Turning SLIs Into Alerts That Actually Fire on Time
- Choosing Telemetry Without Adding Detection Lag
- Testing Your Monitoring Before You Trust It
- From Detection to Containment: Roles That Remove Friction
- How Netverge's Playbooks Put These Tactics Into Practice
- Where to Start If You Can Only Change Three Things
- See These Tactics Running on Netverge
- FAQ
- Sources
What Is MTTD and How Do You Measure It?
Mean time to detect is the average interval between when a problem actually begins and when your monitoring surfaces it to a human or an automated response system. The formula is simple: sum the detection times across incidents, then divide by the number of incidents. The hard part is picking accurate timestamps.
Detection time usually comes from alert-firing timestamps in your monitoring platform, correlated against the first abnormal data point in metrics, logs, or traces. When the true incident start is unclear, use the earliest telemetry anomaly you can verify rather than a customer report, which tends to lag the real onset.
A short instrumentation checklist keeps MTTD honest:
- Record the first anomalous data point, not just the alert-fire time.
- Timestamp alert acknowledgment separately from detection.
- Align clocks across services using a single source like NTP.
- Log dependency failures so you can trace cascading incidents to their origin.
Why Reducing MTTD Matters for Reliability and Cost
Detection time sets the floor for everything that follows. You cannot fix what you have not found, so MTTD directly caps how fast your mean time to resolve can possibly be, and it determines how much blast radius an incident accumulates before anyone responds.
Slow detection also has quieter costs. On-call engineers who get paged late scramble under pressure, postmortems lose fidelity because early signals went unrecorded, and SLO error budgets burn faster during the undetected window.
Alerts that never prompt a human investigation or mitigation create pure noise, and that noise is what burns out on-call staff over time, according to Google's SRE book on monitoring distributed systems. Every minute spent chasing a non-actionable page is a minute not spent catching the next real incident sooner.
Core Strategies to Cut Detection Time Now
A handful of changes account for most of the improvement teams see in practice. Work through them in order of effort versus payoff.
- Switch to symptom-based alerts. Alert on user-facing symptoms like elevated latency or error rate rather than a dozen per-component thresholds that all fire for the same root cause.
- Instrument the golden signals. Track latency, traffic, errors, and saturation for every critical service, and add synthetic checks on the user journeys that matter most to the business.
- Enrich alert payloads automatically. Attach trace IDs, recent deploy tags, and a direct runbook link so the first responder has context before they open a terminal.
- Automate initial triage. Use labels, priority scoring, and pre-filled runbook steps so the assigned engineer starts diagnosing instead of searching.
Consolidating noisy per-component alerts into fewer, symptom-focused ones is usually the single biggest lever, because it removes the duplicate pages that bury the one alert that actually mattered. Our guide to building alerts that prompt real investigation walks through this consolidation in more detail.
Enrichment is the part teams skip most often, and it is also the cheapest to add. A trace ID and a deploy tag in the alert payload can cut the first five minutes of any investigation down to zero, since the responder already knows what changed and where to look. Automated triage tools, including AI-driven labeling and routing, extend that same logic across an entire ticket queue, as covered in our overview of intelligent alerting.

Pro Tip: Route every new alert through a two-question test before it goes live: does it map to a user-visible symptom, and does the payload tell the responder what to do next?
Turning SLIs Into Alerts That Actually Fire on Time
The most reliable pattern for balancing fast detection against false pages is the multi-window burn-rate alert. You compare error-budget consumption over a short window and a long window simultaneously, and you only page when both agree that the budget is burning too fast. This structure achieves a better balance of precision and recall than single-threshold alerts, according to Google's SRE workbook on alerting on SLOs.
- Use a short window (around 5 to 60 minutes) to catch fast-moving incidents.
- Pair it with a longer window (several hours) to confirm the trend before paging.
- Reserve paging for high-severity burn rates; route slower burns to a ticket instead.
- For low-traffic services, widen the aggregation window so single requests cannot trigger a page.
| Burn rate severity | Typical window pair | Response type |
|---|---|---|
| Fast burn | Short + medium window | Page immediately |
| Slow burn | Medium + long window | Ticket, review within hours |
| Sparse traffic | Extended long window | Ticket only, avoid paging |
PromQL-based alerting in Cloud Monitoring supports these multi-window comparisons natively and documents the evaluation-interval trade-offs that determine how quickly a burn-rate alert can realistically fire.
Choosing Telemetry Without Adding Detection Lag
Not every signal arrives at the same speed, and picking the wrong one for alerting adds avoidable delay. Metrics-based monitoring gives you near real-time detection and should drive your paging logic. Logs carry higher fidelity but often incur more ingestion and processing delay, which makes them better suited to root-cause work after an alert fires, per Google's SRE workbook on monitoring.
- Use metrics and synthetic checks for the alert trigger itself.
- Reserve logs and traces for the investigation that follows detection.
- Design alerting metrics to move meaningfully only when the system is genuinely degraded, and keep high-cardinality debug metrics out of the paging path.
- Attach a trace ID, the active deploy tag, and recent config changes to every alert payload so the investigation starts with context already in hand.
Real-world detection scenarios, including the specific signals that caught each incident, are broken down in our network anomaly detection examples. Full-stack visibility matters here too, since detection gaps often trace back to blind spots rather than slow telemetry, a point echoed in Monobot's writing on observability.
Testing Your Monitoring Before You Trust It
An alert you have never tested is an assumption, not a safeguard. Validate monitoring pipelines with a three-tier approach before relying on them in production.
- Binary tests confirm the metric itself reports correctly under known conditions.
- Rule evaluation tests feed synthetic time series through your alert rule to confirm it fires at the right threshold.
- Routing tests verify the alert actually reaches the right person or queue.
Running scheduled validation exercises, including synthetic time series, catches silent monitoring failures before a real incident exposes them, per Google's SRE workbook on monitoring. A weekly test run, ideally wired into CI, keeps this discipline from slipping once the initial setup is done.
From Detection to Containment: Roles That Remove Friction
Catching an incident fast only helps if the handoff into response is just as fast. Clear roles and a shared source of truth prevent the confusion that quietly extends detection into a longer outage.
- Assign an incident commander to own coordination, not technical fixes.
- Keep a living incident document that every responder updates in real time.
- Define trigger rules for declaring an incident early, before severity is fully confirmed.
- Practice handoffs and role assignments periodically through role-play drills.
Clear incident command roles prevent duplicated effort and keep incident state intact across handoffs, which shortens the effective path from detection to containment, according to Google's SRE book on managing incidents. Our network incident response guide includes templates for the living document and role assignments described here.
Pro Tip: Write your trigger rules for declaring an incident before you need them. Deciding severity thresholds mid-crisis almost always delays the declaration.
How Netverge's Playbooks Put These Tactics Into Practice
Our playbooks apply this checklist in the field with a 90-day first-response plan sequencing symptom-based alerting, enrichment, and automated triage into a rollout order MSPs can follow without disrupting existing operations, detailed in our guide to cutting first response time. A companion playbook on false-alarm reduction walks through consolidating per-component alerts, the same pattern covered in the core strategies above, in our piece on cutting alert fatigue.
On the product side:
- Unified telemetry dashboards combine metrics, logs, and device status to help responders avoid switching tools mid-incident.
- Vergepoint hardware sensors provide on-site, real-time visibility at the network edge.
- AI-powered ticket triage applies automated labeling and priority assignment to incoming alerts.
Where to Start If You Can Only Change Three Things
Start with symptom-based SLO alerts, add one synthetic check on your most critical user flow, and validate a single alert end to end with the three-tier test. Measure the MTTD change before adding more. Keep every alert actionable, and rotate on-call roles so the discipline survives staff turnover.
— Jim
See These Tactics Running on Netverge
Unified telemetry, AI-driven triage, and Vergepoint hardware sensors bring the symptom-based alerting and enrichment practices above into one dashboard instead of five disconnected tools.
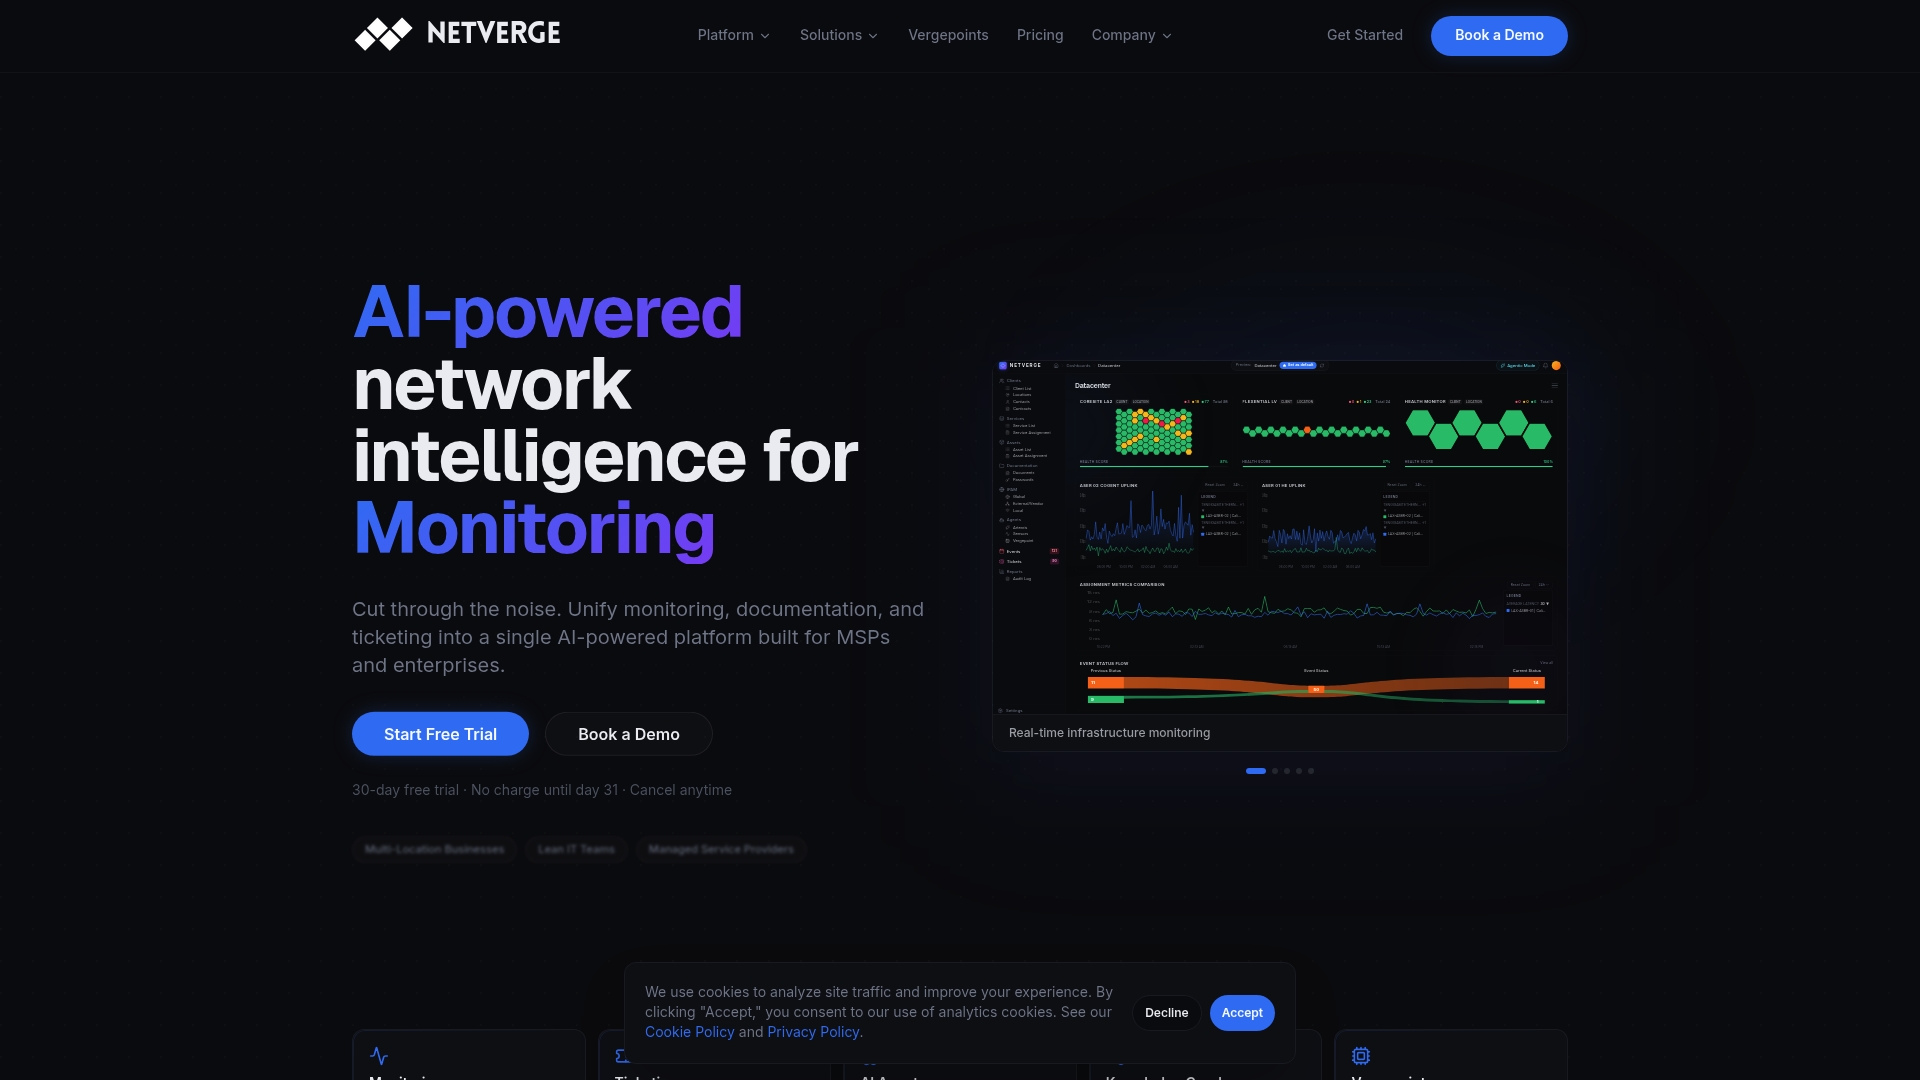
Our Starter Package starts the AI-powered monitoring and triage setup described throughout this guide, and you can explore Hardware Vergepoints and related add-ons if edge visibility is the gap you need to close first. Start a free trial to see how it fits your current alert setup.
FAQ
How is MTTD measured?
MTTD is the average time between when an incident actually begins and when monitoring or a human detects it, calculated by summing detection times across incidents and dividing by the incident count. Accuracy depends on using the earliest verifiable anomaly timestamp rather than a customer-reported time, which tends to lag the real onset.
Which metrics include MTTD, MTTI, MTTR, and MTTV?
These are part of the same incident-lifecycle family: MTTD (mean time to detect) measures how fast you spot a problem, MTTI (mean time to identify or investigate) measures how fast you diagnose the cause, MTTR (mean time to resolve or repair) measures how fast you fix it, and MTTV covers time to verify or validate the fix. Together they map the full timeline from onset to confirmed resolution.
What does MTTR stand for in the context of cybersecurity?
In cybersecurity and IT operations, MTTR most commonly stands for mean time to resolve, the average time from detecting a security incident to fully containing and remediating it. Some teams use it to mean mean time to respond, referring specifically to the time between detection and the start of active mitigation.
How do you determine MTTR?
You calculate MTTR by summing the resolution times for a set of incidents and dividing by the number of incidents, using the same start and end timestamp conventions your team applies to MTTD. Keeping detection and resolution timestamps clearly separated matters, since mixing them inflates one metric while deflating the other.