SLA monitoring is the continuous, automated tracking of service level agreement metrics against contracted targets, using tools that pull data from ticketing systems, network telemetry, and synthetic checks. If you check one thing today, check whether your SLA clocks and ticket sync are accurate. A large share of breaches are false alarms caused by broken integrations, not real service failures. Modern monitoring pairs ITIL 4 discipline with automation and AI to catch problems before they become violations.
TL;DR:
- Ensuring SLA clocks and ticket synchronization are accurate is crucial, as most breaches often stem from broken integrations rather than actual service failures.
- Monitoring should focus on availability, mean time to restore customer-impacting service, response and resolution times, error rates, latency, throughput, and security indicators, segmented by customer tier and service type.
- Setting measurable SLA targets requires analyzing historical data, defining clear measurement rules, and establishing escalation and clock-pause procedures to avoid common measurement mistakes.
- Combining AI, automation, and real-time monitoring of infrastructure, synthetic checks, and integration health helps prevent breaches and ensures trustworthy reporting.
- Internal focus should be on visibility, clock accuracy, and data integrity first, with automation and prevention strategies prioritized over adding numerous dashboards.
Table of Contents
- What SLA Monitoring Actually Covers
- Key SLA Metrics You Must Monitor
- How To Set Measurable SLA Targets And Measurement Rules
- Tools, Automation, And AI For SLA Monitoring
- Preventing, Detecting, And Investigating SLA Breaches
- Operationalizing SLA Monitoring With ITIL 4 And Integration Ops
- A Practitioner's Take On What Actually Moves The Needle
- How Netverge Helps You Operationalize SLA Monitoring
- Sources
What SLA Monitoring Actually Covers
SLA monitoring, SLA management, and the acronyms surrounding both get blurred together constantly, and that confusion causes real operational damage. Getting the vocabulary right matters because vague terms lead to vague measurement, and vague measurement leads to disputes with customers who feel shortchanged even when you technically hit your numbers.
Here's how the terms actually break down:
- SLA (Service Level Agreement): The contractual document defining what service you promise, to whom, and what happens if you miss it.
- SLO (Service Level Objective): The specific, measurable target inside that agreement, such as "99.9% uptime" or "first response within 15 minutes."
- SLI (Service Level Indicator): The actual measured value, pulled from monitoring tools, that tells you whether you're hitting the SLO.
- XLA (Experience Level Agreement): A newer layer that measures how the service feels to the end user, not just whether the ticket closed on time.
SLA management is the broader discipline: negotiating terms, setting pricing, reviewing renewals, and handling disputes. SLA monitoring is the operational layer underneath it, the part that watches clocks tick and fires alerts. You can manage an SLA badly even while monitoring it perfectly, and vice versa.
In practice, measurement points come from three places: incident and ticket timestamps in your ITSM platform, synthetic checks that simulate a user logging in or running a transaction, and real end-user transaction traces that capture what an actual customer experienced. Relying on only one of these gives you a partial picture. A synthetic check might show a login page loading fine while real users on a congested branch link wait eight seconds, a gap only end-to-end tracing catches.
Key SLA Metrics You Must Monitor
You don't need forty dashboards. You need a handful of metrics that map directly to what your customer actually cares about, measured consistently and reported honestly.
IBM's guidance on SLA metrics narrows the essential list down to five categories, and each one deserves a specific measurement approach rather than a generic percentage:
- Availability/uptime: Usually calculated as a percentage of total time the service was reachable, but the nuance is in what counts as "down." Scheduled maintenance windows and third-party outages typically get excluded from the calculation, and that exclusion needs to be spelled out in the contract, not assumed.
- Mean time to restore service (MTRS) vs. MTTR: These get used interchangeably, and that's a mistake. MTTR (mean time to repair) measures how long the technical fix took. MTRS measures how long the customer was without usable service, including detection lag and communication delays. MTRS is the number that reflects actual customer impact, and it's usually the larger figure.
- First response time and resolution time: How fast someone acknowledges the ticket, and how fast the issue actually gets closed. These get tracked separately because a fast acknowledgment with a slow fix still frustrates customers.
- Error rates, latency, and throughput: Especially relevant for network and application SLAs, where designing the SLA around business-relevant metrics like packet loss and jitter matters more than a raw uptime percentage that ignores degraded performance.
- Security and compliance indicators: Patch cadence, incident disclosure timelines, and audit response times increasingly show up as their own SLA line items, particularly for regulated clients.
Pro Tip: Segment every one of these metrics by customer tier and service type before you report on them. A single blended average across your whole client base hides the fact that your platinum-tier accounts are breaching while your standard accounts are fine, or the reverse.
One statistic worth internalizing: integration and data synchronization failures account for a large share of ITSM SLA violations in practitioner research, meaning the metrics above are often measuring broken pipelines rather than broken service. Before you trust a breach report, verify the data feeding it.
How To Set Measurable SLA Targets And Measurement Rules
Setting an SLA target by guessing at a round number is how you end up contractually obligated to something you can't deliver. Follow a structured process instead.
- Pull historical performance data first. Look at your actual response and resolution times over the last two to three quarters before committing to a number. If your median resolution time is four hours, promising two hours across the board sets you up to fail on day one.
- Define business hours versus calendar hours explicitly. A "4-hour resolution" target means something completely different if it only counts business hours (9 to 5, Monday through Friday) versus running around the clock. Write this distinction directly into the SLA document, not into a separate internal policy nobody outside your team sees.
- Establish clock-pause rules. SLA clocks should pause when you're waiting on the customer for information, waiting on a third-party vendor, or during a mutually agreed maintenance window. Failing to pause the clock during these waits is one of the most common measurement mistakes teams make, and it inflates your breach count with delays you didn't cause.
- Write the measurement method into the contract, not just the target. State exactly which tool captures the timestamp, how downtime gets calculated, and what counts as an exclusion. Document supporting OLAs (Operational Level Agreements between internal teams) and underpinning contracts (agreements with third-party vendors) so everyone knows who's accountable for each leg of the process.
- Build escalation rules tied to percentage-of-SLA-consumed, not just the final deadline. A notification at 75% of the allotted time and another at 90% gives your team a chance to act before the clock runs out, not after.
Pro Tip: Treat your SLA target as an acceptable range rather than a single number. Consistently beating your target by a wide margin sounds great until the customer starts expecting that pace permanently, and one bad week suddenly looks like a dramatic failure instead of a return to baseline.
Tools, Automation, And AI For SLA Monitoring
Most SLA monitoring stacks pull from four categories of tooling, and the gaps between them are where breaches slip through unnoticed. ITSM and ticketing platforms track the contractual clock. Observability tools capture infrastructure metrics like CPU, bandwidth, and error rates. Synthetic transaction monitors simulate user actions on a schedule. End-to-end tracing follows a real request across every system it touches, which is the layer most teams skip until something goes wrong.
Automation is what turns raw data into a monitoring system instead of a reporting archive. A few patterns are worth building into any setup:
- Threshold alerts at 75% and 90% of SLA time consumed, escalating automatically to a supervisor if the 90% mark is crossed with no acknowledgment.
- Auto-escalation rules that reroute a stalled ticket to a different technician or team after a defined idle period.
- SLA clock synchronization across tools, so a ticket that moves from your monitoring platform to your ticketing system to a vendor's portal keeps a single, accurate timestamp instead of three conflicting ones.
AI adds a layer on top of that automation rather than replacing it. AI-enabled SLA management shifts the model from reactive reporting to proactive orchestration: predictive alerts flag tickets likely to breach before they do, automated triage routes issues to the right team on first contact instead of after a bounce or two, and reply-suggestion tools cut the time a technician spends drafting a first response. Ticket deflection, where common issues get resolved through self-service before they ever consume SLA time, reduces volume on the metrics you're tracking in the first place.
None of this works if the integration layer underneath is unreliable. Idempotent retries (so a repeated sync attempt doesn't create duplicate tickets), message queuing (so a brief outage doesn't drop events entirely), and observability on the integrations themselves, not just the services they connect, are what keep your SLA data trustworthy. Testing frameworks like those offered through automated integration testing services can catch sync failures before they corrupt a reporting period.
Preventing, Detecting, And Investigating SLA Breaches
Most breaches trace back to one of four root causes: integration drift between systems that were synced correctly at setup but have quietly diverged since, misrouted alerts that never reached the right technician, ownership gaps where nobody was formally accountable for a ticket type, or misconfigured clocks that never got the business-hours or pause rules applied correctly.
Prevention starts before a breach happens, not after. Run end-to-end integration tests on a regular schedule rather than only when something breaks. Monitor the sync pipelines themselves, not just the systems they connect, so a silent failure in your ticketing-to-monitoring handoff gets caught in minutes instead of discovered by an angry customer three days later. Build redundant alerting paths so a single failed notification channel doesn't mean nobody hears about a critical issue.
When a breach does get reported, work through it in order:
- Verify the measurement first. Before assuming a real breach occurred, confirm the SLA clock ran correctly, applied the right pause rules, and pulled data from the correct source system.
- Reconstruct the timeline using timestamps from every system the ticket touched, not just the final one.
- Check integration logs for sync failures, dropped events, or duplicate records around the time in question.
- Correlate the ticket data against infrastructure and network metrics to see whether the breach lines up with a real technical incident or just a reporting gap.
- Document root cause and corrective action once the real cause is confirmed, then route it through a governance review so the fix actually sticks.
Pro Tip: Keep a running log of "false breach" investigations separately from real ones. If integration failures keep showing up as the cause quarter after quarter, that's a signal to fix your data pipeline, not your service delivery.
A network incident response process built around this same sequence, verify, reconstruct, correlate, document, tends to close investigations faster because nobody wastes time debating whether the breach was real.
Operationalizing SLA Monitoring With ITIL 4 And Integration Ops
ITIL 4 frames Service Level Management as the practice responsible for setting, negotiating, monitoring, and reporting on service targets, and it explicitly recommends backing every customer-facing SLA with internal OLAs and vendor-facing underpinning contracts. That structure matters because an SLA promised to a customer is only as reliable as the weakest internal handoff supporting it.
The practice guide also points to using the four dimensions of service management, organizations and people, information and technology, partners and suppliers, and value streams and processes, as a lens for reviewing SLA performance. Instead of asking "did we hit 99.9%," ITIL 4 pushes teams to ask whether the target still reflects actual business value, or whether it's just a number everyone stopped questioning years ago.
On the integration side, the practical fixes for stopping breaches "at the source" include:
- Building redundant integration paths so one failed connector doesn't take down your entire sync pipeline.
- Monitoring integration health in real time, treating sync status as its own SLA-relevant metric.
- Automating failover so a broken connection reroutes to a backup path without manual intervention.
Tracking MTRS trends and SLA achievement rate over time, rather than just the current period's number, is what feeds continual improvement. A single quarter's data tells you whether you hit target. A rolling trend tells you whether your process is actually getting better or just riding out a lucky stretch.
A Practitioner's Take On What Actually Moves The Needle
Most SLA monitoring advice tells you to buy more dashboards. That's backwards. The teams I've seen make real progress fixed their integration visibility and clock accuracy first, before adding a single new report. If your sync pipeline is silently dropping events or double counting pause time, no amount of dashboard polish fixes the underlying number.
The second lever is restraint: pick a small set of SLIs that tie directly to what the customer experiences, MTRS over MTTR, real response time over vanity uptime, and ignore the temptation to track everything your tools happen to expose. More metrics without more clarity is just noise with a nicer chart.
Automation for prevention beats automation for reporting, every time. Predictive alerts and auto-escalation stop breaches before they're logged. A prettier post-mortem report just documents them faster. That's the order I'd tackle it in, and it happens to be the same order a unified platform like Netverge is built around: visibility and integration integrity before dashboards, prevention before reporting.
— Jim
How Netverge Helps You Operationalize SLA Monitoring
Netverge gives MSPs and multi-location IT teams the unified visibility that SLA monitoring actually depends on, one platform pulling network telemetry, ticketing data, and integration health into a single view instead of three disconnected tools quietly drifting out of sync.
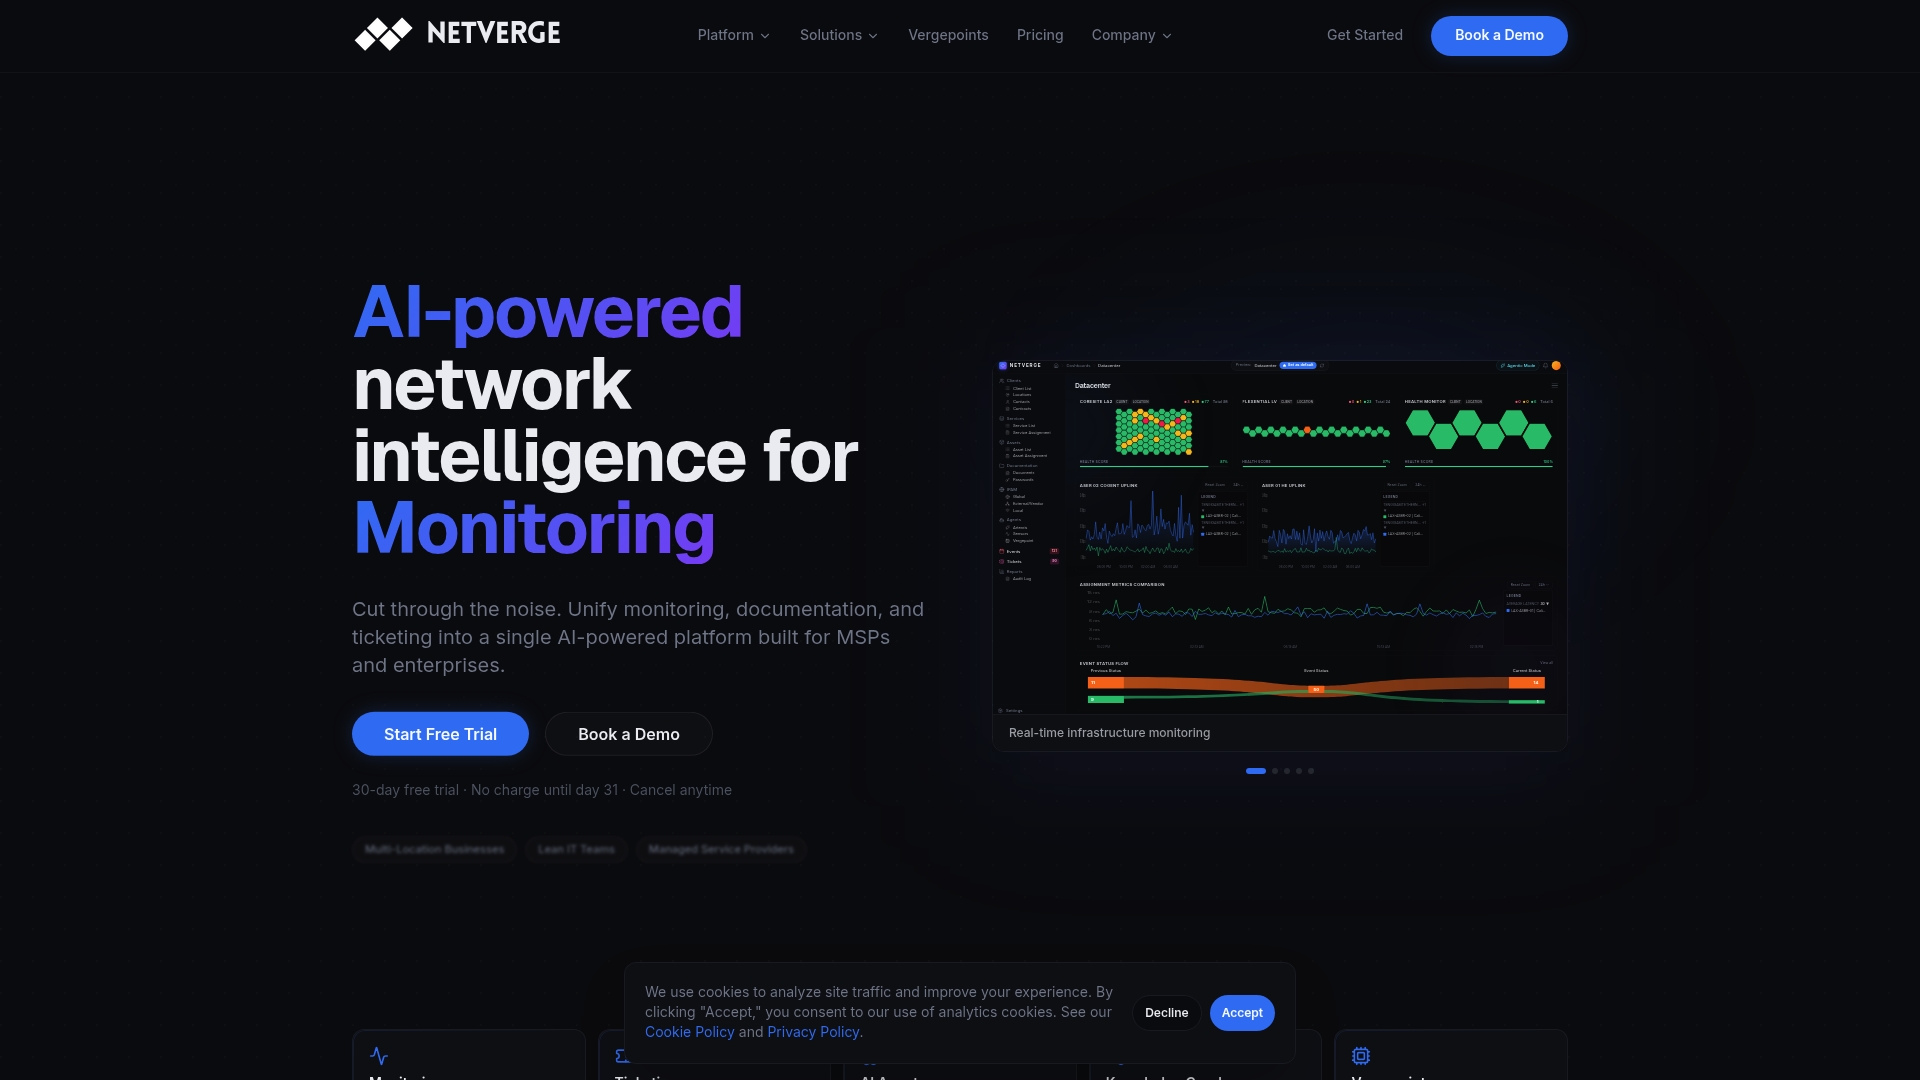
That consolidation matters because, as the earlier sections covered, most SLA breaches trace back to broken pipelines rather than broken service. Netverge's AI-powered ticketing and service desk automatically tracks SLA clocks against ticket status, applies pause rules consistently, and triages incoming issues so response times reflect real technical work, not queue delays. Paired with AI-powered network monitoring and observability, teams get fewer false breaches, faster escalation on issues that matter, and reporting that holds up when a customer questions a number. If your SLA reporting currently means exporting three spreadsheets and reconciling timestamps by hand, requesting a Netverge demo is the faster path to a single, trustworthy source of truth.
Sources
- What is ITIL 4 Service Level Management? SLAs, metrics and practice guide
- 5 SLA metrics you should be monitoring