A branch monitoring appliance is an on-site hardware node deployed at a remote office that collects LAN, WAN, and packet-level telemetry and forwards it to a central SaaS platform. For MSPs and multi-site IT teams, the outcome is straightforward: one unified view of every branch, faster troubleshooting, and policy enforcement that stays consistent no matter how many sites you manage.
TL;DR:
- Branch monitoring appliances provide critical east-west traffic telemetry, enabling detection of lateral movement and internal threats often missed by perimeter security.
- Telemetry should include throughput, latency, jitter, packet loss, DNS, TLS logs, and flow data, with local environmental sensors for hardware health and power status.
- Out-of-band management and zero-touch provisioning are essential for scalable deployment across multiple sites, reducing onsite staffing needs and support costs.
- Operations benefit from automated alert correlation, baseline anomaly detection, and automated remediation to minimize mean time to detection and resolution.
- Full telemetry and automation should be tested in pilots before wide deployment to ensure noise reduction and effective root cause identification in complex multi-site networks.
Table of Contents
- How a branch monitoring appliance fits into SD-Branch networking
- Core capabilities and telemetry a branch monitoring appliance should provide
- Security and compliance patterns tied to branch monitoring
- Deployment and operations: hardware, provisioning, and resiliency
- Metrics, alerting, and automation to reduce MTTD and MTTR
- Evaluation checklist for MSPs and multi-site IT teams
- Case studies and real-world use cases for branch monitoring
- What experienced teams get wrong about branch monitoring
- How Netverge solves the branch monitoring appliance problem
- Sources
- FAQ
How a branch monitoring appliance fits into SD-Branch networking
Branch monitoring appliances are not a replacement for SD-WAN or SD-Branch architecture. They are the observability layer that makes those architectures trustworthy at scale. An SD-branch collapses routing, switching, Wi-Fi, and security functions into a centrally managed platform designed for rapid deployment and consolidated control. A monitoring appliance sits alongside that infrastructure, watching how it actually performs rather than just enforcing configuration.
Routers and firewalls answer the question "is traffic allowed through?" A monitoring appliance answers a different question: "what is actually happening on this network right now?" That distinction matters when a branch reports slow application performance but every device on the SD-WAN dashboard still shows green.
Centralized management is not a convenience feature. CISA's guidance on centralized management and telemetry recommends that distributed organizations monitor data flows at points that cannot be easily bypassed, which is precisely the role a physical appliance plays at the branch edge. Without it, you are relying on the network gear's own reporting, which tends to be incomplete during the failures that matter most.
For MSPs managing dozens or hundreds of client sites, this architectural layering also determines how support tickets get resolved. A practical guide to SD-WAN monitoring walks through how these layers interact in day-to-day operations.

Core capabilities and telemetry a branch monitoring appliance should provide
Not every device marketed as a monitoring tool captures the telemetry that actually matters when something breaks. A branch appliance worth deploying should give you visibility into throughput, jitter, packet loss, and latency at minimum, along with flow-level detail through NetFlow or sFlow and application-layer signals from DNS and TLS logs.
East-west visibility deserves particular attention. Lateral movement between devices inside a branch rarely shows up in north-south traffic monitoring, which is why packet-level inspection at the branch edge is necessary to catch threats that traditional perimeter tools miss.
A complete capability set typically includes:
- Topology mapping and device discovery that stays current without manual entry.
- Local environmental sensors covering power state, link status, and hardware health.
- Flow and packet telemetry spanning both north-south and east-west traffic.
- Documentation integration so discovered devices and configurations sync automatically into your knowledge base.
Teams managing many sites often underestimate how much time manual documentation consumes. A look at multi-location visibility requirements covers how this plays out when site counts climb into the hundreds.
Security and compliance patterns tied to branch monitoring
Branch telemetry is only half the value proposition. What you do with it inside your security stack determines whether monitoring actually reduces risk or just generates dashboards nobody checks.
CISA's joint guide on modern secure network access recommends FWaaS, ZTNA, and hardware-enforced segmentation as core elements of modern branch security, typically bundled into SASE or SSE architectures. A monitoring appliance's telemetry becomes far more useful when it feeds directly into those services rather than sitting in an isolated dashboard.
The TIC 3.0 Branch Office Use Case defines branch trust zones and calls for central logging, continuous monitoring, and policy enforcement points at each branch, a framework that maps closely onto how a monitoring appliance should operate in practice.
Patterns worth building into your deployment:
- Feed telemetry into SASE/SSE analytics rather than keeping it siloed at the branch.
- Enforce policy centrally so a compromised or misconfigured branch device cannot bypass inspection.
- Centralize logs for SOC and NOC teams, preserving forensic detail for incident response.
- Capture packets selectively at trust-zone boundaries defined by TIC 3.0 guidance.
Deployment and operations: hardware, provisioning, and resiliency
Rolling out monitoring appliances across dozens of branches fails when it depends on skilled staff physically present at each site. The operational model that scales looks different.
- Standardize on zero-touch or one-touch provisioning so a non-technical person on-site can rack the device and have it phone home for configuration.
- Build template policies once and apply them fleet-wide, adjusting only site-specific exceptions.
- Deploy out-of-band management so you retain control of the appliance even when the primary WAN link fails. Out-of-band management gives you BIOS-level access independent of the production network path.
- Plan physical placement and power carefully, including UPS backup, before shipping hardware.
- Run a pilot at three to five sites before committing to a full rollout, and use that pilot to validate provisioning time and support load.
Pro Tip: Pair out-of-band management with local health sensors so a remote reboot or BIOS-level recovery is possible without a truck roll.
Cost drivers to watch include per-device hardware fees, additional sensor packs as fleets grow, and the staffing hours needed for the pilot phase. Vergepoints hardware is built for this kind of plug-and-play deployment, which reduces the provisioning burden discussed above.
Metrics, alerting, and automation to reduce MTTD and MTTR
Telemetry without disciplined alerting just produces noise. The metrics worth tracking against SLA commitments are latency, packet loss, jitter, and availability, each with thresholds tuned to the application sensitivity of the branch rather than a single blanket number across the fleet.
The bigger operational challenge is noise. A branch generating hundreds of low-severity alerts a day trains staff to ignore all of them, including the one that matters. Reducing that noise requires correlation across related signals, anomaly detection that flags deviation from a site's own baseline rather than a fixed threshold, and triage that groups related alerts into a single incident.
- Correlate related alerts into one incident instead of paging on every individual signal.
- Baseline anomaly detection per site rather than applying one threshold fleet-wide.
- Automate low-risk remediation such as interface resets or service restarts, with human approval gates on anything touching production routing.
- Use a knowledge graph to connect an alert to the device history and prior resolutions, cutting diagnosis time.
A workflow guide for setting SLA thresholds covers how operations teams tune these numbers without drowning in false positives.
Evaluation checklist for MSPs and multi-site IT teams
Before signing a contract or committing budget, run the appliance and its accompanying SaaS through this sequence.
- Confirm multi-tenancy and role-based access work cleanly across client boundaries or business units.
- Verify provisioning model supports zero-touch or one-touch setup at remote sites without a specialist on-site.
- Check telemetry completeness, including east-west visibility, packet capture, and DNS/TLS logging.
- Validate security integrations, particularly log forwarding into SASE, SSE, or SIEM tooling already in use.
- Review hardware requirements, including power draw, out-of-band management, and rack space.
- Test API and integration depth against your existing documentation and ticketing systems.
Skipping the telemetry completeness check is the most common mistake. Appliances that look identical on a spec sheet often differ sharply in east-west visibility once deployed.
Case studies and real-world use cases for branch monitoring
The clearest ROI signal from branch monitoring deployments shows up in how quickly a distributed team can isolate a problem to a single site instead of investigating the entire network. An MSP managing retail chains, for example, typically fields recurring complaints about point-of-sale slowness that turn out to be a single misconfigured switch port at one location rather than a WAN-wide issue. Packet-level telemetry at the branch edge turns that kind of investigation from a multi-hour escalation into a five-minute lookup.
Multi-site enterprises with regional offices face a similar pattern with Wi-Fi and VPN complaints that get escalated to headquarters IT without enough detail to act on. Local sensors covering power and link state let a NOC confirm within minutes whether a report is a hardware issue, a WAN problem, or a device misconfiguration, before dispatching anyone on-site.

The broader lesson across these situations is consistent: value comes from cutting the time between a symptom being reported and a root cause being confirmed, not from adding another dashboard. Distributed organizations that rely on SaaS applications at every branch cannot depend on SD-WAN telemetry alone to catch these issues, since SD-WAN without integrated observability leaves blind spots at exactly the layer where end users experience problems.
What experienced teams get wrong about branch monitoring
The most common mistake I see is treating north-south traffic monitoring as sufficient and skipping east-west visibility entirely, which leaves lateral movement and internal misconfigurations invisible until they cause an outage. A close second is skipping out-of-band management, which turns a routine WAN outage into a truck roll. Fragmented dashboards compound both problems by hiding the correlation that would otherwise catch an issue early.
My recommendation: pilot with full telemetry enabled and automated triage running before committing to a fleet-wide rollout. The pilot tells you whether the noise reduction actually works before you scale it to a hundred sites.
— Jim
How Netverge solves the branch monitoring appliance problem
Netverge combines Vergepoints hardware with an AI-powered SaaS layer, so the telemetry gaps and dashboard fragmentation covered above do not have to be solved with separate tools. Vergepoints deliver real-time four-way monitoring at the branch edge, while the platform's knowledge graph and autonomous AI agents handle correlation and ticket triage centrally, cutting the manual work of chasing down which site actually has the problem.
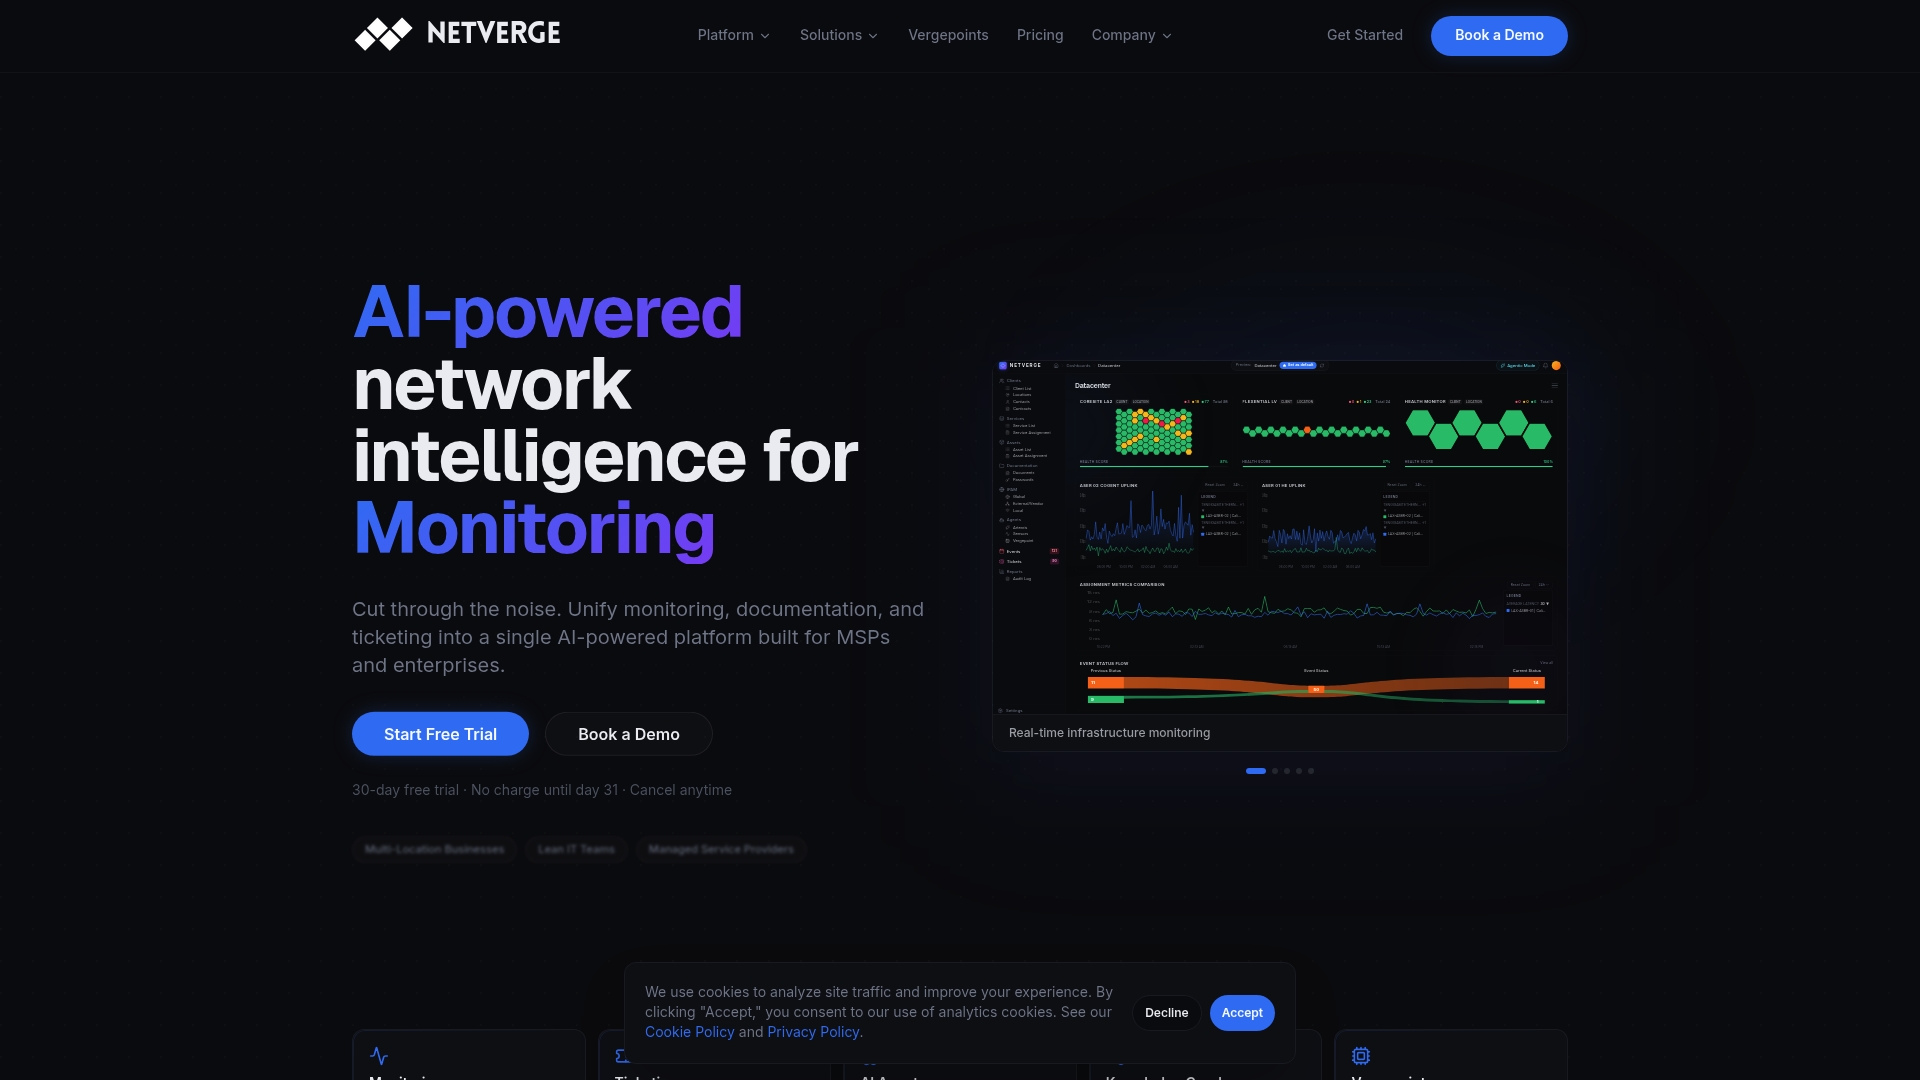
For MSPs juggling multi-tenant client environments, that means one console instead of a dozen fragmented tools. For multi-site enterprises, it means consistent policy enforcement without hiring a specialist at every branch. The Starter Package is priced at $299 per month, with Hardware Vergepoints available at $49 per month per device for teams ready to deploy on-site sensors.
If you manage more than a handful of sites and are still stitching together separate monitoring, documentation, and ticketing tools, start a free trial and see how the consolidated view changes your triage time.
Sources
For deeper reading, CISA's TIC 3.0 branch office guidance and SD-branch fundamentals from TechTarget cover the architecture and compliance angles in more detail than fits here.
- What is an SD-branch? | Definition from TechTarget
- How to protect the crown jewels with east-west network visibility (NetworkComputing)
- What is out-of-band management? (Intel)
FAQ
What does a branch monitoring appliance actually monitor?
It monitors LAN and WAN performance, including throughput, latency, jitter, and packet loss, along with flow data and DNS or TLS logs at the branch edge. Many appliances also capture east-west traffic and local hardware health, such as power and link status.
Is a branch monitoring appliance the same as an SD-WAN device?
No, an SD-WAN device handles routing and connectivity, while a monitoring appliance focuses on observability and telemetry collection. They typically work alongside each other rather than replacing one another, as described in TechTarget's SD-branch overview.
How much does Netverge's branch monitoring hardware cost?
Netverge's Hardware Vergepoints are priced at $49 per month per device, with a Software Vergepoint option available at $29 per month per vergepoint. The Starter Package platform subscription is $299 per month, listed on Netverge's pricing page.
Why does east-west visibility matter for branch security?
East-west visibility catches lateral movement between devices inside a branch that north-south perimeter monitoring typically misses. Packet-level inspection at the branch edge is necessary to detect this kind of internal traffic pattern.