Syslog monitoring gives you central visibility into what your routers, firewalls, servers, and applications are doing, and it turns scattered log lines into alerts and evidence you can act on. The right approach: accept both RFC 3164 and RFC 5424 messages, but emit RFC 5424 wherever you control the sender. Encrypt everything in transit with TLS, deploy edge collectors to handle scale, and filter noise at the source before it ever reaches central storage.
TL;DR:
- Accepts both RFC 3164 and RFC 5424 formats, normalizing legacy logs to ensure compatibility across a mixed-device network.
- Uses TLS over port 6514 for secure transport of security-critical logs, while TCP port 514 remains common but unencrypted.
- Implements tiered collection with edge relays and persistent queues to handle scale, outages, and maintain data integrity.
- Combines severity, facility, and host role for alerting to reduce noise and prioritize critical incidents effectively.
- Employs an integrated platform that automates collection, parsing, and AI-assisted triage, minimizing manual configuration and scalability issues.
Table of Contents
- What Is Syslog Monitoring and Why It Still Matters
- RFC 3164 vs. RFC 5424: Which Format Should You Use?
- How Do You Architect Syslog Collection for a Large Network?
- Keeping Syslog Data Secure and Trustworthy
- How Do You Set Up and Operate a Syslog Collector?
- How Should You Set Up Alerts Without Drowning in Noise?
- What IT Teams Get Wrong About Syslog
- A Faster Path Than Building Your Own Pipeline
- Sources
- FAQ
What Is Syslog Monitoring and Why It Still Matters
A syslog pipeline has three roles: the originator (the device generating the message), the relay (a node that forwards or repairs it), and the collector (where it lands for storage and analysis). Common originators include routers, switches, firewalls, load balancers, and any Linux or Unix server running rsyslog or syslog-ng.
Every syslog message carries a PRI value, calculated as facility multiplied by 8 plus severity. Severity alone is a weak signal. A severity 3 ("error") from a lab switch means something very different than the same severity from a core firewall, so reliable alerting requires combining severity with facility and host identity, not severity in isolation.
Before turning on monitoring log files at scale, run through this quick checklist:
- Inventory every device that can emit syslog, including appliances people forget (UPS units, wireless controllers, hypervisors).
- Confirm each source's clock is synced to NTP. Unsynced clocks make correlation nearly impossible.
- Decide which facility codes matter for security versus operations.
- Identify which devices only support RFC 3164 so your collector knows to normalize them.
RFC 3164 vs. RFC 5424: Which Format Should You Use?
RFC 5424 is the current IETF standard and effectively replaces the older RFC 3164 BSD-style format. It adds structured data fields, full RFC3339 timestamps with timezone and sub-second precision, and UTF-8 encoding. RFC 3164 uses free-form ASCII text and timestamps with no year or timezone, which is exactly why so many legacy devices still produce logs that are hard to correlate at scale.
You will not get to choose a single format across a real network. Older switches and appliances often ship with RFC 3164 hardcoded, while modern firewalls and cloud-native services default to RFC 5424. The practical answer is to accept both formats and normalize at the relay, converting legacy messages to RFC 5424 for storage.
Transport choice matters just as much as format:
| Transport | Port | Use case | Reliability/security |
|---|---|---|---|
| UDP | 514 | Legacy senders, low overhead | No delivery guarantee, no encryption |
| TCP | 514 (convention) | Reliable delivery, common default | Guaranteed delivery, plaintext |
| TLS over TCP | 6514 | Security-critical or compliance-relevant logs | Encrypted and authenticated |
Plain TCP on port 514 is a widespread convention, not a formal standard, and it still sends data in the clear. RFC 5424 recommends TLS transport for exactly that reason: anything touching authentication events, firewall denies, or admin activity belongs on port 6514 with TLS enabled.
How Do You Architect Syslog Collection for a Large Network?
A single collector works fine for a handful of devices. It falls apart once you're pulling from dozens of sites or thousands of endpoints, which is where a tiered design earns its keep. NIST SP 800-92 describes exactly this kind of layered log management infrastructure, splitting responsibilities across generation, collection, and analysis tiers.
- Edge relay tier: Sits close to the source devices, filters obvious noise, and buffers during network hiccups.
- Central ingest tier: Receives filtered streams from every edge relay, indexes them, and feeds your SIEM or analytics platform.
- Persistent queue layer: Sits at both tiers to absorb bursts and outages without dropping data.
Sizing depends on message rate per node and average payload size, but common signs that you're underprovisioned include growing queue backlog, rising latency between event time and arrival time, and TCP connections pinning to a single collector instead of spreading load. Native syslog load balancing at the relay tier prevents that pinning problem before it becomes an outage.
Persistent queues (PQ) on the source side matter more than most teams realize. When a central collector goes down for maintenance, a PQ on the relay holds messages locally instead of silently dropping them, which is the difference between a blip and a gap in your evidence trail.
Pro Tip: Graph queue depth over time, not just its current value. A queue that's climbing steadily, even slowly, tells you a downstream tier can't keep pace, long before you'd notice from dropped-packet counters alone.
Keeping Syslog Data Secure and Trustworthy
Treat your collectors as high-value security assets, not utility infrastructure. A compromised collector means compromised evidence, and evidence you can't trust in an investigation is worse than no evidence at all.
- Encrypt everything security-relevant in transit. Use TLS on port 6514 for authentication logs, firewall events, and anything that might end up in an investigation. Reject plaintext connections for that traffic entirely.
- Harden the collector itself. Isolate it on its own segment, restrict administrative access to a small named group, and run the syslog service under a least-privilege account rather than root.
- Detect silent loss actively. Monitor packet receive errors, watch for gaps between expected and actual message rates per source, and alert when queue metrics spike or arrival timestamps start lagging generation timestamps.
- Align retention with your actual needs. Set retention windows based on how long a typical investigation takes and what your compliance framework requires, not an arbitrary default.
Encrypted, authenticated transport and collector hardening are now treated as baseline controls for security and compliance programs, not optional upgrades you get to when time allows. Syslog remains the lowest common denominator for telemetry across mixed vendor environments, which makes preserving its evidence quality more important than simply capturing more of it.
How Do You Set Up and Operate a Syslog Collector?
Standing up a receiver takes more than opening a port. Follow this sequence and you'll avoid the most common first-week failures:
- Open the right ports and certs first. Allow UDP 514 for legacy senders, and provision valid TLS certificates for port 6514 before pointing any critical device at the collector.
- Sync time everywhere. Every source and every collector needs NTP. Mismatched clocks break correlation before you've written a single alert rule.
- Set your parsing policy. Accept RFC 3164 and RFC 5424 both, convert legacy messages to RFC 5424 on ingest, normalize all timestamps to UTC, and confirm UTF-8 encoding survives the conversion.
- Filter and enrich at the source. Drop debug-level chatter before it leaves the relay, and tag high-value events (auth failures, config changes, interface flaps) so they're easy to query later.
- Harden the host. Lock down administrative access, run the service with a dedicated low-privilege account, and disable anything you don't need running on that box.
Once it's live, watch these numbers daily: kernel receive buffer utilization (net.core.rmem_max is the sysctl setting to tune under sustained UDP load), netstat receive error counts, and persistent queue depth on both relays and central ingest.
Pro Tip: If UDP receive errors climb during business hours but not overnight, you're almost certainly buffer-limited, not bandwidth-limited. Raising the kernel buffer size usually fixes it faster than adding hardware.
How Should You Set Up Alerts Without Drowning in Noise?
Raw syslog volume is useless until you map it to response tiers. Combine severity, facility, and host role into a single alert tier: a critical severity from a core router pages someone immediately, while the same severity from a test VLAN switch might just open a ticket.
- Page-worthy: Authentication failures exceeding a threshold in a short window, a monitored device going unreachable, or unexpected changes to firewall or router configs.
- Ticket-worthy: Isolated warnings, single failed logins, or non-critical service restarts that don't repeat.
- Correlate before you page. Group related events (five failed logins across three devices in two minutes) and require a threshold or sequence match rather than firing on every single line.
For post-incident work, retain full raw logs long enough to cover your typical investigation window, and archive summarized or aggregated data beyond that for trend analysis. A tool like real-time monitoring workflows built around these tiers cuts down the noise that buries genuine incidents.
What IT Teams Get Wrong About Syslog
Most teams over-invest in collecting more data and under-invest in trusting the data they already have. Every conversation defaults to "let's ingest everything," when the harder and more valuable question is whether a given log stream can survive a collector outage, a clock skew, or a format mismatch without silently losing events. Volume without integrity checks isn't observability. It's just a bigger haystack.
The other blind spot: teams treat RFC compliance as a checkbox instead of a parsing strategy. Real networks run a messy mix of RFC 3164 relics and RFC 5424 modern devices for years, and pretending otherwise leads to brittle parsers that break the moment someone racks a new switch. Netverge's approach reflects that reality by unifying telemetry, automating triage, and preserving evidence quality across mixed-format sources rather than forcing a single standard on every device in the stack.
— Jim
A Faster Path Than Building Your Own Pipeline
Building a compliant syslog pipeline from scratch means stitching together relays, persistent queues, TLS certificates, and parsing rules, then maintaining all of it as your device count grows. Netverge replaces that piecemeal build with a unified platform that handles collection, parsing, and alerting in one place.
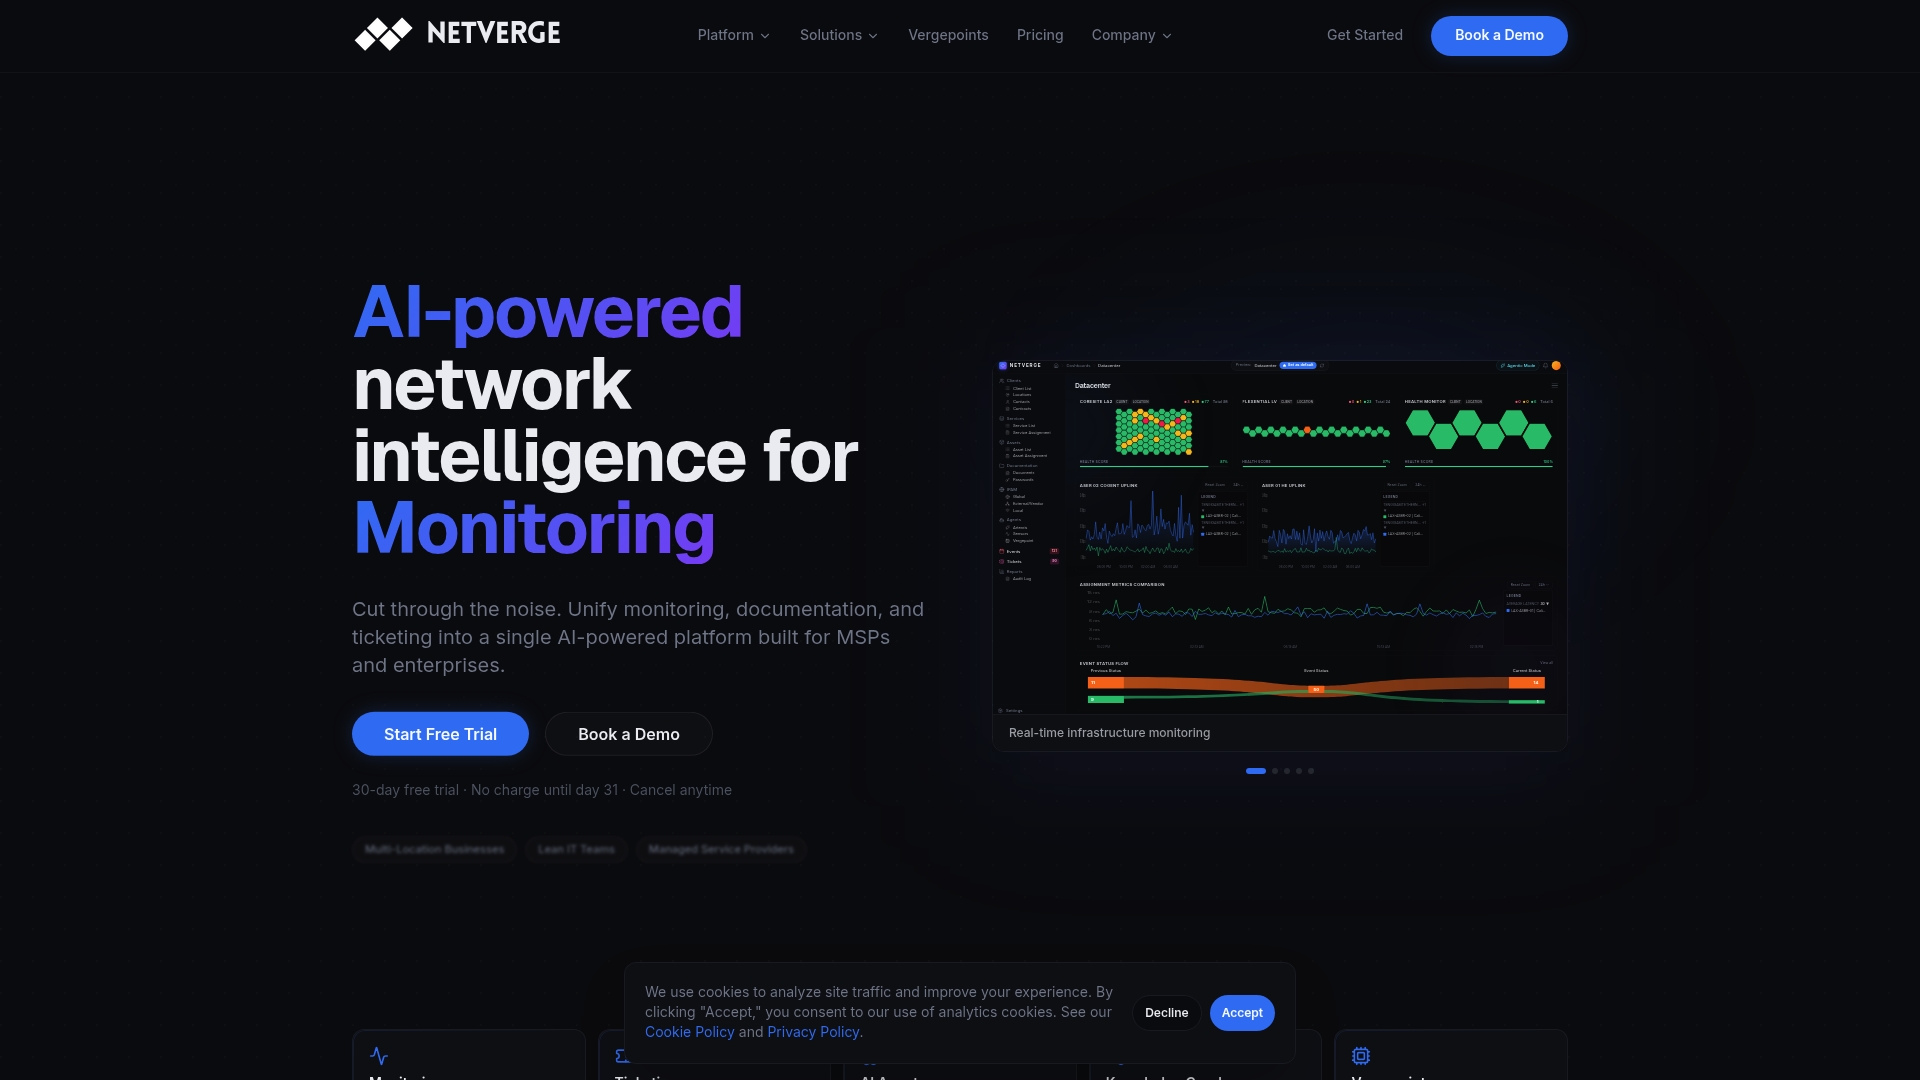
The platform normalizes mixed RFC 3164 and RFC 5424 sources automatically, applies AI-assisted ticket triage so alerts reach the right person without manual severity mapping, and preserves evidence quality during investigations. For sites where you need physical, on-location visibility instead of relying purely on remote polling, Vergepoints give you edge collection and buffering without deploying a separate relay stack. If you're an MSP managing this across multiple client networks, or an enterprise running dozens of sites, an integrated monitoring platform will scale further than a hand-built pipeline before you ever have to re-architect it. Request a demo to see how your existing syslog sources map onto Netverge's dashboards and knowledge graph.
Sources
For the technical detail beyond this guide, start with RFC 5424 for the modern syslog specification and RFC 3164 for the legacy BSD format it replaced. NIST SP 800-92 covers log management architecture in depth, and the operational tuning guides from Graylog and Cribl are worth bookmarking for buffer sizing and persistent queue configuration.
- RFC 5424 - The Syslog Protocol
- NIST Special Publication 800-92: Guide to Computer Security Log Management
- Syslog protocol: a reference guide | Graylog
- Syslog server best practices: setup, tuning, and scaling | Cribl
FAQ
How Do I Check My Syslog?
On Linux, check /var/log/syslog or /var/log/messages directly, or query your centralized collector if you're already forwarding logs there. Most collectors also expose a search interface, which is faster once you have more than a couple of devices reporting.
What Is SIEM vs. Syslog?
Syslog is a transport and message format for log data; a SIEM is a platform that ingests logs (often via syslog), correlates them across sources, and generates security alerts. Syslog monitoring typically feeds a SIEM rather than replacing it.
What Are the Downsides of Using Syslog?
Syslog has no built-in delivery guarantee over UDP, weak native security unless you layer on TLS, and inconsistent formats across RFC 3164 and RFC 5424 devices that complicate parsing. High volume from noisy sources can also bloat storage and slow analysis if you don't filter at the source.
What Is the Difference Between Syslog and Rsyslog?
Syslog refers to the protocol and message format defined by RFC 3164 and RFC 5424; rsyslog is a specific software daemon that implements syslog collection, forwarding, and filtering on Linux systems. Rsyslog is one of several tools, alongside syslog-ng and commercial collectors, that speak the syslog protocol.
Does Netverge Support Syslog Monitoring Directly?
Netverge ingests syslog data alongside other network telemetry, applying AI-assisted triage and unified dashboards so teams don't need a separate standalone syslog server for basic visibility.