The fastest fix is a dedicated backlog recovery lane paired with Level 1 automation, run separately from your live queue. This article walks through the audit, the triage rules, the automation sequence, the metrics that prove progress, and the prevention cadence that keeps the queue from refilling.
TL;DR:
- Automate password resets and monitoring alert creation to achieve a 30-40% reduction in ticket volume within one to two weeks.
- Use category-based batching and timeboxing during recovery to close progress gaps in 20 to 45 days, with strict escalation and reassignment rules.
- Implement a triage system that separates severity, urgency, and customer segment to prioritize tickets and escalate aging issues automatically.
- Track daily burn-down rates, inflow versus outflow, and age distribution to ensure backlog decline and prevent new growth.
- Deploy a unified monitoring and ticketing platform to attach diagnostic context automatically, accelerating diagnosis and reducing backlog buildup.
Table of Contents
- How Do You Reduce Ticket Backlog in 30, 60, and 90 Days?
- How Should You Triage a Large Ticket Backlog?
- Which Automations Cut Backlog Fastest, and How Do You Trust Them?
- What Self-Service Tactics Actually Deflect Tickets?
- What Metrics Prove Your Backlog Is Actually Shrinking?
- How Do You Staff a Backlog Recovery Without Adding Headcount?
- How Do You Stop the Backlog From Coming Back?
- How a Unified Monitoring Stack Shortens Diagnosis and Routing
- What Trade-offs Should You Actually Expect During a Burn-Down?
- Get Started With Netverge for Backlog Recovery and Prevention
- Sources
- FAQ
How Do You Reduce Ticket Backlog in 30, 60, and 90 Days?
Clearing a backlog that has grown to hundreds or thousands of open tickets is not a matter of working faster. It requires separating recovery work from live support, then attacking the backlog with rules that prevent it from reforming. Here is the sequence that works.
Days 1 to 10: Audit and categorize. Pull every open ticket and slice it by three dimensions: category (password reset, network outage, hardware failure, access request), age bucket, and current blocker (waiting on customer, waiting on vendor, waiting on internal approval). This backlog report becomes your map. Without it, you are guessing at priority, and guessing is how backlogs grow in the first place.
Calculate your backlog percentage right away: open tickets divided by total tickets received in the same period, multiplied by 100.
Days 10 to 20: Stand up a dedicated recovery lane. Practitioner guidance from managed service provider operations consistently points to the same fix: pull two or three agents off the live rotation and assign them exclusively to backlog clearance, ideally during your lowest-volume hours. A dedicated recovery lane run during low-volume windows clears old tickets faster than spreading the work across an already-stretched team, and it protects your live queue's service level agreements from collateral damage. Staff this lane with a mix of one senior agent who can make judgment calls on stale tickets and one or two junior agents who handle the templated closures.
Days 20 to 45: Batch and timebox. Break the backlog into two-hour sprints organized by category, not by ticket age. Closing twenty password reset tickets in one sitting is faster than jumping between five categories. Set a hard stop for each sprint. When agents know a batch ends in two hours, they move with more urgency.
- Sort backlog by category and assign one category per sprint block.
- Cap each sprint at two hours with a visible countdown for the team.
- Route anything that can't close within the sprint to a "needs escalation" tag instead of letting it linger untouched.
- Reassign tickets sitting with an unresponsive owner for more than five business days.
- Run a daily 15-minute standup during the recovery phase to unblock stuck tickets immediately.
Days 45 to 90: Close, merge, retire. Not every open ticket deserves individual attention. Build a bulk-close template for categories where the fix is already known and confirmed working: "This issue was resolved on [date] as part of a broader fix. Reply within 5 business days if you're still experiencing this problem." Use it for tickets tied to a resolved outage, a patched vulnerability, or a deprecated feature.
- Merge duplicate tickets tied to the same root cause into a single parent ticket before closing the children.
- Retire tickets for decommissioned hardware or software with a note explaining why.
- Flag any ticket older than 30 days for manager review before bulk-closing it, since older tickets carry higher customer-relationship risk.
- Log every bulk-close batch size and category so you can measure the burn-down rate week over week.
Escalation handoffs need their own internal SLA during this window. If a recovery-lane agent cannot resolve a ticket within one sprint, it goes to a named second-tier owner within four business hours, not "whenever someone gets to it." Vague handoffs are exactly how a cleared backlog rebuilds itself within a quarter.
Pro Tip: Track your daily burn-down rate (tickets closed minus tickets reopened) on a shared dashboard the whole team can see. Visible progress keeps a recovery lane motivated in a way that a spreadsheet buried in a shared drive never will.
How Should You Triage a Large Ticket Backlog?
Not every ticket in a backlog deserves the same response speed, and treating them equally is the single most common reason recovery efforts stall. A workable triage framework separates severity (how broken is it), urgency (how fast does it need fixing), and customer segment (who is affected and what is their contract tier).
- Severity measures technical impact: is a service down, degraded, or cosmetically broken?
- Urgency measures time sensitivity: does this block someone's workday right now, or can it wait a week?
- Customer segment determines the response floor: an enterprise account on a premium support tier gets a different clock than a self-service user.
Combine severity and urgency into an impact-times-urgency score, and layer age-based escalation on top of it. A medium-severity ticket that has sat untouched for 20 days should automatically escalate even if it originally scored lower than a fresh high-severity ticket. Age alone is a signal that something in your process is broken, and ignoring it is how tickets quietly age into the 31-plus day bucket that drags down every backlog metric you report.
Duplicate detection matters more in a backlog than in live queues, because backlogs accumulate duplicate reports of the same underlying issue over weeks. Build a rule that flags tickets with matching keywords, affected systems, or timestamps within a tight window, and consolidate them before they eat two agents' worth of time separately.
During triage, capture fields that automation can act on later: affected system, error code, customer tier, and whether the fix is "known" or "needs investigation." A structured triage process that captures these fields consistently is what makes auto-routing and auto-resolution possible in the next phase. Skip this step and every automation project downstream inherits messy, unusable data.
Which Automations Cut Backlog Fastest, and How Do You Trust Them?
Start with the highest-volume, lowest-risk categories, not the flashiest AI features. Password reset requests alone often account for 30 to 50% of Level 1 ticket volume, which makes self-service password reset the single highest-return automation most support teams can deploy, typically within one to two weeks.
Automate in this order:
- Password and access resets through self-service portals.
- RMM-to-PSA ticket creation, so monitoring alerts generate tickets automatically instead of waiting for a human to notice and log one.
- Status update automation, so customers get progress notifications without an agent typing the same update fifty times a week.
- Macros and canned responses for the ten most repeated ticket types in your backlog report.
- AI-based classification and routing for tickets that don't match a simple keyword rule.
Foundational automations like RMM-to-PSA integration and self-healing scripts reduce ticket volume by 30 to 40% in typical MSP environments. Combined with AI-driven classification, one ACM-published study measured a 30% drop in average resolution time and a 35% drop in backlog after intelligent routing replaced manual assignment.
Roll out AI triage in stages instead of flipping it on for every ticket type at once. First, let the model observe and classify tickets in read-only mode while agents still make the actual routing decision. Compare the model's suggested category against what the agent actually chose for two to four weeks. Once accuracy on a given category consistently matches or beats manual routing, let the model auto-route those tickets without a human check. Reserve auto-resolution, where the system closes a ticket without agent review, for the lowest-risk categories only, such as password resets and known-issue notifications.
Set a guardrail before auto-resolution goes live: track the reopen rate on auto-closed tickets weekly. If reopens climb above your reopen rate on agent-closed tickets, pull the category back to auto-route-only until you retrain the classification rules. This single check protects customer trust while the automation matures. Detail on validating AI triage accuracy in live network operations is worth reviewing before your first rollout, since the guardrails that matter for network incidents apply just as directly to general support queues.
What Self-Service Tactics Actually Deflect Tickets?
Your backlog report already tells you which categories to target for deflection: whatever shows up most often with a known, repeatable fix is a candidate for a knowledge base article or an in-product help panel, not another round of manual replies.
- Write knowledge base articles using the exact language customers use in their tickets, not internal jargon, since search matching depends on word overlap.
- Place help links directly inside the product screen where the problem occurs, not buried three clicks deep in a general help center.
- Use a chatbot or virtual agent for Level 1 deflection on high-volume, low-complexity categories like password resets and account status checks.
- Assign one owner per knowledge base category and review article accuracy monthly, since stale KB content actively generates more tickets than it prevents.
Self-service and knowledge base investment tends to be the most durable lever available, often cutting volume by 40 to 60% for targeted categories once articles are aligned to actual ticket language. Broader deflection benchmarks put the payoff threshold around 30% deflection before cost improvements become significant.
Pro Tip: Measure deflection by tracking how many customers view a KB article before submitting a ticket on the same topic, then submit anyway. A high "viewed but still submitted" rate means the article isn't actually answering the question.
What Metrics Prove Your Backlog Is Actually Shrinking?
Backlog percentage is your headline number: open tickets divided by total ticket volume in the period, times 100. Track it weekly, not monthly, during an active recovery push, because monthly reporting hides a backlog that quietly grows for three weeks before the数字 catches up.
Ticket age distribution matters just as much as the raw count. Break every open ticket into buckets and watch how the distribution shifts week over week:
| Age bucket | What it signals | Target during recovery |
|---|---|---|
| — | Healthy, normal flow | Majority of open volume |
| — | Needs attention soon | Shrinking week over week |
| 30 | At risk, escalation candidate | Declining steadily |
| 31+ days | Chronic backlog, root-cause signal | Near zero outside known exceptions |
Inflow versus outflow is the number that tells you whether you're actually winning. If outflow (tickets closed per day) doesn't exceed inflow (new tickets per day) by a meaningful margin, your recovery lane is treading water no matter how busy it looks.
- Build a daily burn-down chart plotting inflow against outflow, visible to the whole team.
- Track AI deflection rate: the share of contacts resolved without a human agent.
- Track misrouting rate on auto-routed tickets to catch classification drift early.
- Build an SLA compliance heatmap by category to spot which ticket types are quietly missing targets.
Forrester's service-desk benchmarking research is a useful reference point when setting realistic staffing assumptions and backlog targets for your own reporting to leadership, since internal targets set without external context tend to be either too lenient or unrealistically aggressive.
How Do You Staff a Backlog Recovery Without Adding Headcount?
A dedicated recovery lane beats rotating assignments for one simple reason: rotation means every agent context-switches between live urgent work and backlog cleanup, and context-switching is slow. Dedicated staffing, even for two-hour blocks, keeps focus intact.
- Assign two to three agents to the recovery lane during your lowest-volume hours, based on historical ticket patterns.
- Pair one senior agent with one or two junior agents per sprint, so junior staff handle templated closures while seniors make judgment calls on ambiguous tickets.
- Align staffing to known inflow peaks. If Mondays and post-holiday weeks reliably spike, add temporary recovery capacity ahead of those windows rather than reacting after the queue balloons.
- Cap consecutive recovery shifts at two per agent per week to avoid burnout from repetitive closure work.
- Rotate the recovery lane roster every two weeks so no single agent absorbs all the tedious cleanup long-term.
Category-specific staffing alignment, matched to predictable weekday and seasonal peaks, keeps recovery lanes appropriately sized instead of overstaffed on quiet days and underwater during predictable surges.
How Do You Stop the Backlog From Coming Back?
Clearing a backlog without fixing what caused it is a temporary win. Within two quarters, most teams that skip root-cause work find themselves back where they started, often worse, because the recovery effort taught nobody anything about why tickets piled up in the first place.
Tag every backlog ticket with a root-cause category during closure: known bug, missing documentation, unclear product behavior, or process gap. After a few weeks of consistent tagging, you'll see concentration. Typically, a small number of root causes drive a disproportionate share of ticket volume; that concentration is exactly what tells you where to send engineering resources first instead of spreading fixes thin across every complaint.
- Track repeat-driver concentration monthly and rank root causes by ticket volume, not by how loud the complaint was.
- Route the top two or three root causes to product or engineering as prioritized fix requests, with the ticket volume attached as justification.
- Set a weekly backlog review meeting focused purely on age and inflow, separate from any incident review.
- Hold a monthly root-cause-analysis session where each recurring issue gets a named owner and a target resolution date.
- Revisit SLAs for ticket categories that consistently miss targets. Sometimes the fix is a faster process, sometimes it's an honest SLA adjustment.
Decommission ticket categories tied to retired products or features entirely rather than letting them linger as a permanent trickle nobody owns. A category with three tickets a month that nobody is actively fixing is a slow leak, and slow leaks compound over a year into a backlog you didn't see building.
Pro Tip: Assign a single "prevention owner" for your top three root causes, separate from whoever handles day-to-day ticket triage. Splitting recovery work from prevention work keeps both from getting starved when things get busy.
Change management matters here too. A team that just spent 90 days grinding through a backlog burn-down needs a new steady-state process, not a return to the old habits that created the backlog. Document the new triage rules, the escalation SLAs, and the automation guardrails as your team's actual working process, and train new hires on it directly instead of letting institutional knowledge live only in a few senior agents' heads.
How a Unified Monitoring Stack Shortens Diagnosis and Routing
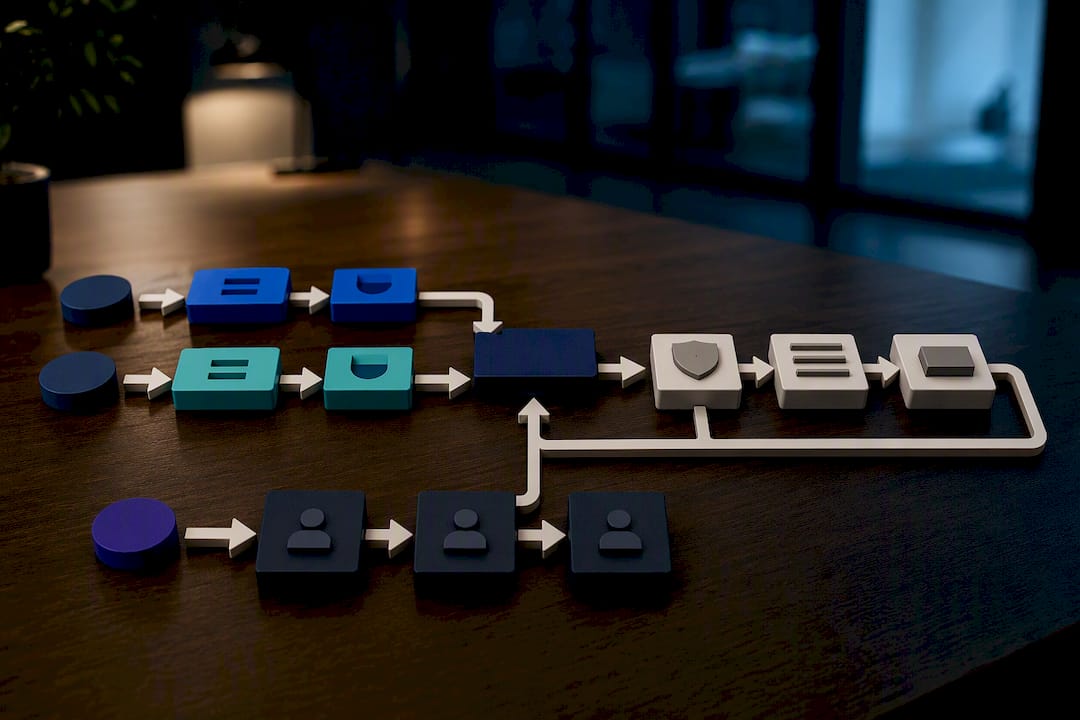
Backlog often grows because context is scattered: monitoring in one tool, documentation in another, tickets in a third. A consolidated stack closes that gap by attaching diagnostic context to a ticket the moment it's created, rather than making an agent hunt for it.
A typical flow looks like this: a Vergepoint sensor detects an anomaly on-site, a ticket is generated automatically with the relevant telemetry attached, AI triage classifies and routes it based on severity and historical resolution data, and a human agent picks it up with full context already in hand instead of starting from a blank ticket.
That sequence is what separates fast resolution from a backlog that quietly grows one under-contextualized ticket at a time.
What Trade-offs Should You Actually Expect During a Burn-Down?
Bulk-closing is fine for confirmed, resolved issues with a clear customer notification path. It is not fine for anything ambiguous. Closing an uncertain ticket to hit a number damages customer satisfaction faster than a slow queue ever will.
Set two separate targets: a temporary recovery goal to clear the existing pile, and a sustainable backlog percentage you intend to hold afterward. Conflating the two confuses stakeholders about what "done" actually means.
Report progress with the burn-down chart, not a single before-and-after number. Stakeholders trust a trend line they can watch move over trusting a claim made once at the end.
— Jim
Get Started With Netverge for Backlog Recovery and Prevention
A unified platform consolidates monitoring, documentation, and ticketing tools that typically operate separately. Instead of an agent piecing together context from three systems before touching a backlog ticket, Netverge attaches monitoring data, historical resolution patterns, and AI triage decisions to the ticket automatically, which is exactly the kind of consolidation this playbook depends on for fast, safe recovery.
If you're running the 30/60/90 plan above, Netverge's AI-powered ticketing and service desk module handles the classification and routing steps directly, and Vergepoints hardware gives your recovery lane the on-site telemetry needed to close tickets without back-and-forth troubleshooting. The Starter Package is $299 per month, with Hardware Vergepoints and Software Vergepoints priced separately on the pricing guide for teams scaling sensor coverage.
Run your backlog audit against a live Netverge dashboard by starting a free trial this week, and see how much of your current triage work the platform can absorb before your next recovery sprint.
Sources
- The state of the service desk (Forrester)
- ACM study on AI-enhanced ticket management
- Customer Support Benchmarks 2026
FAQ
What Does "Ticket Backlog" Mean?
A ticket backlog is the set of support or IT tickets that remain open past their expected resolution window, typically anything unresolved beyond your team's standard service level. It's measured as backlog percentage: open tickets divided by total tickets received, multiplied by 100.
What Are the Different Types of Backlog?
Backlogs generally break into categories by cause: incident backlog (unresolved outages or errors), request backlog (access, provisioning, or change requests), knowledge-gap backlog (tickets stalled on missing documentation), vendor-dependent backlog (waiting on a third party), and stale-ownership backlog (tickets with no active owner). Segmenting your backlog report by these categories, rather than treating it as one undifferentiated pile, is what makes prioritization possible.
How Do You Beat a Large Backlog Fast?
The fastest approach combines a dedicated recovery lane staffed separately from live support, batch closing of tickets in timeboxed sprints, and Level 1 automation for high-volume categories like password resets. Practitioner data shows this combination, layered with AI classification and routing, can reduce backlog by 30 to 55% within 30 to 90 days.
What's a Healthy Backlog Percentage to Target?
Benchmarks from Forrester's service desk research are a useful reference for setting a target that matches your team's actual staffing and ticket volume.
Does Netverge Help With Backlog Reduction?
Yes. Netverge's AI triage classifies and routes tickets automatically, and Vergepoints hardware attaches live monitoring context to tickets the moment an issue is detected, which shortens the diagnosis time that typically stalls backlog recovery. Current pricing, including the Starter Package and add-on hardware, is listed on Netverge's pricing guide.